AEO content gap analyzer with n8n


An AEO content gap analyzer built with n8n finds the buyer questions where AI assistants give a confident answer but never mention or cite you, then tells you what to write to fix it. Tracking your AI visibility shows you where you stand; this workflow turns the misses into a plan. Each week it asks a grounded AI your buyer questions, isolates the ones where you are absent while competitors are cited, and drafts a short content brief for each gap so you have a working title and an angle. It logs the whole backlog to Google Sheets and emails you the week’s opportunities. The build takes about 45 minutes, or a couple of minutes with the template at the end.

What it does

Each week the workflow sends a set of neutral buyer questions to Google Gemini with search grounding, so every answer comes back with the live web sources it used. For each question it checks two things: does the answer mention your brand, and do the cited sources include your domain. When the answer is no on both, that question is a gap, a topic where the AI has decided someone else is the authority.

For every gap, the workflow makes a second AI call that reads the question and the sources currently winning it, then writes a short content brief: a suggested article title and four points to cover. Each gap becomes a row in a Google Sheets backlog with the question, who is cited now, the suggested title, and the full brief. At the end you get one email listing the week’s content opportunities, ranked and ready to hand to a writer.

This is the action layer of AEO, answer engine optimization. It closes the loop opened by the rest of the set: the brand-mention tracker, the competitor visibility monitor, and the AI citation monitor tell you where you stand; this one tells you what to do about it. New to n8n? Start with how to set up n8n.

Why it beats the default

The default content plan is a guess. You brainstorm topics, write what feels important, and hope AI answers and search pick them up. You have no signal about which questions you are actually losing, and no idea who is beating you on them. Checking by hand means opening an assistant, asking a question, noticing you are missing, and forgetting about it by the next meeting.

This workflow replaces the guess with evidence. It only surfaces questions where you are genuinely absent, shows the sources that own them today, and hands you a brief so there is no blank page. Paid AEO platforms offer gap reports, but they cost a monthly subscription and rarely draft the fix for you. This runs on your prompts, writes to a sheet you own, and costs pennies a week. For more AI workflows you can import, see the best n8n AI agent templates and the full template library.

What you need

  • An n8n instance (Cloud or self-hosted, version 1.0 or newer).
  • A Google Gemini API key with grounding available (free tier includes a daily grounding allowance). Used as an HTTP Header Auth credential with header x-goog-api-key.
  • A Google account for Sheets and a Gmail account for the report.
  • A blank Google Sheet with a header row matching the field names below (or a Notion database if you prefer, see the tip).
  • Your brand name, your domain, and a list of buyer questions.

Time: about 45 minutes from scratch, or under 5 minutes with the template.

Node-by-node list

Nine nodes: a schedule, a config node, a grounded AI call, a gap filter, a brief-writing AI call, a formatter, and a fork that logs and emails.

Weekly schedule (Mon 7am)
        |
   Prompts & config  (Code)
        |
   Ask Gemini (grounded)  (HTTP: answer + sources)
        |
   Find gaps  (Code: keep only questions you are absent from)
        |
   Draft content brief  (HTTP: AI writes a brief per gap)
        |
   Format brief  (Code: build the backlog row)
        |          |
 Log to Sheets   Build digest
                     |
            Send digest email (Gmail)
  
  1. Weekly schedule (Schedule Trigger) fires every Monday at 7am.
  2. Prompts & config (Code) holds your brand, domain, and buyer questions.
  3. Ask Gemini (grounded) (HTTP Request) answers each question with sources.
  4. Find gaps (Code) keeps only the questions where you are absent.
  5. Draft content brief (HTTP Request) asks the AI to write a brief for each gap.
  6. Format brief (Code) turns each brief into a clean backlog row.
  7. Log backlog to Sheets (Google Sheets) appends the gaps.
  8. Build digest (Code) rolls the gaps into one report.
  9. Send digest email (Gmail) emails you the opportunities.

Step-by-step build

1. Add the weekly schedule

Add a Schedule Trigger, interval Weeks, every 1 week, day Monday, hour 7. A weekly cadence gives you a steady trickle of gaps to work through rather than an overwhelming list.

2. Set your brand, domain, and prompts

Add a Code node. It emits one item per question and carries your brand and domain so the gap filter can check both.

const BRAND = 'Acme Analytics';
const DOMAIN = 'acmeanalytics.com';
const PROMPTS = [
  'What are the best analytics tools for a small ecommerce store?',
  'How do I track marketing ROI for a SaaS startup?',
  'What is a good tool for automated weekly sales reports?',
  'How do small teams build a KPI dashboard without engineers?',
  'Best alternatives to a spreadsheet for tracking business metrics?'
];
return PROMPTS.map(p => ({ json: { prompt: p, brand: BRAND, domain: DOMAIN } }));

3. Ask Gemini with grounding

Add an HTTP Request node, method POST, with a Header Auth credential storing your key under x-goog-api-key. Grounding is turned on with the google_search tool so the answer carries its sources:

URL:  https://generativelanguage.googleapis.com/v1beta/models/gemini-2.5-flash:generateContent

JSON body:
={{ JSON.stringify({
  contents: [ { parts: [ { text: $('Prompts & config').item.json.prompt } ] } ],
  tools: [ { google_search: {} } ]
}) }}

4. Find the gaps

Add a Code node. It reads every answer, checks whether your brand is in the text or your domain is in the sources, and keeps only the questions where both are missing.

const cfg = $('Prompts & config').all().map(i => i.json);
const ans = $('Ask Gemini (grounded)').all().map(i => i.json);
const brand = String(cfg[0].brand).toLowerCase();
const domain = String(cfg[0].domain).toLowerCase();

const out = [];
for (let i = 0; i < cfg.length; i++) {
  const cand = ans[i]?.candidates?.[0] || {};
  const text = (cand.content?.parts || []).map(p => p.text || '').join(' ');
  const chunks = cand.groundingMetadata?.groundingChunks || [];
  const sources = chunks.map(c => ({ uri: c.web?.uri || '', title: c.web?.title || '' }));
  const inText = text.toLowerCase().includes(brand);
  const inSources = sources.some(s => (s.uri + ' ' + s.title).toLowerCase().includes(domain));
  if (inText || inSources) continue; // you are present, not a gap
  const topSources = sources.slice(0, 5).map(s => s.title || s.uri).filter(Boolean);
  out.push({ json: { prompt: cfg[i].prompt, brand: cfg[0].brand, top_sources: topSources.join(', '), answer_excerpt: text.slice(0, 400) } });
}
return out;
📌

Note: If no gaps are found, this node returns nothing and the rest of the workflow simply does not run, so a quiet inbox means you are already showing up everywhere you tested.

5. Draft a content brief for each gap

Add a second HTTP Request node to Gemini (same Header Auth credential, no grounding this time). It writes a brief per gap, using the question and the sources currently winning it:

JSON body:
={{ JSON.stringify({ contents: [ { parts: [ { text:
  'You are an AEO strategist. A buyer asked an AI: "' + $json.prompt + '". ' +
  'Our brand was not mentioned or cited. Sources cited instead: ' + ($json.top_sources || 'none') + '. ' +
  'Write a content brief for an article that could earn a citation for this query. ' +
  'First line: a suggested article title. Then 4 short bullet points of what to cover. Keep it under 120 words.'
} ] } ] }) }}

6. Format, log, and email

Add a Code node that pairs each brief with its gap and builds a backlog row (date, question, who is cited now, suggested title, full brief). Then add a Google Sheets node (operation Append Row, mapping Map Automatically) with a header row of report_date, question, status, top_cited_sources, suggested_title, content_brief, and a Code plus Gmail pair for the digest. Save and activate.

💡

Tip: Prefer a Notion backlog? Swap the Google Sheets node for a Notion node set to create a database page, and map the same fields to your database properties. The rest of the workflow is unchanged.

Common mistakes

  • Skipping grounding on step 3. Without tools: [{ google_search: {} }] there are no sources, so the domain check always fails and everything looks like a gap.
  • Grounding the brief call in step 5. The brief is pure generation. Leave grounding off there to keep it fast and cheap.
  • Naming your brand in a prompt. It hides real gaps. Prompts must be neutral buyer questions.
  • Treating briefs as final copy. They are a starting angle. The expertise you add on top is what actually earns the citation.
  • Mismatched Sheet headers. Automatic mapping needs exact column names, or columns land blank.

Cost at realistic volume

One grounded call per question, plus one plain call per gap found, one Sheets append per gap, and one email per run.

Service Usage per weekly run (15 questions, ~5 gaps) Cost
Gemini grounded search 15 grounded calls Free daily allowance, then ~$35 / 1,000 prompts
Gemini brief generation ~5 plain calls Fractions of a cent
Google Sheets ~5 row appends Free
Gmail 1 email Free
n8n 1 execution / week Free self-hosted; ~4 executions/month on Cloud

A weekly content backlog built from real AI evidence for a few cents. The paid platforms that produce gap reports start around fifty dollars a month and rarely write the brief for you.

Get the AEO content gap analyzer template

The guide above is free to follow. If you would rather skip the build, the ready-to-import template drops all nine nodes and every script onto your canvas. Import it, add your Gemini, Google Sheets, and Gmail credentials, set your brand and questions, and your first backlog can run today. Want it installed and tuned to your market? Our done-for-you service sets it up end to end.

Download the template ($19) →

Instant download · Works on n8n Cloud and self-hosted

Frequently asked questions

What is an AEO content gap?

It is a buyer question where an AI assistant gives a confident answer but never mentions or cites you, while it does cite competitors or other sources. Each gap is a topic where the AI has decided someone else is the authority. Filling it is how you earn your way into future answers.

How is this different from tracking mentions or citations?

Those tools measure where you stand. This one turns the misses into a plan: it isolates the questions you lose, sees who wins them, and drafts a content brief for each so you know exactly what to publish. It is the do-something step after the measuring steps.

Why does it use grounded search?

Grounding makes Gemini answer from the live web and return the sources it used. That lets the workflow check both the answer text and the cited pages, so a gap means you are truly absent, not just unnamed. Without grounding there would be no source list to compare against.

Are the AI-written briefs good enough to publish from?

Treat them as a starting angle, not a finished article. The brief gives you a working title and the points the winning sources cover, which saves the blank-page step. A human should still add real expertise, data, and examples, which is also what earns the citation.

How many prompts should I run?

Start with ten to twenty questions that map to your core offers. That is enough to surface a handful of real gaps each week without a huge brief list. As you fill gaps, rotate in new questions so the analyzer keeps finding fresh opportunities rather than repeating the same ones.

Related guides

Monitor AI citations of your website with n8n


To monitor AI citations of your website with n8n, you need a workflow that asks a grounded AI real buyer questions and then reads the list of sources it used, checking whether your domain is one of them. This is a step beyond tracking whether an assistant says your name. A citation means the AI actually pulled from your site, trusts it enough to build an answer on, and often links to it, which sends real referral traffic. This guide builds a free workflow that runs weekly, sends your prompts to Gemini with Google Search grounding, records whether your domain and your competitors’ domains are cited, logs every result to Google Sheets, and emails you a citation report. It takes about 40 minutes to build, or a couple of minutes with the template at the end.

What it does

Once a week the workflow sends a set of neutral buyer questions to Google Gemini with search grounding turned on. Grounding makes Gemini search the live web and attach the pages it used as sources, returned in a field called groundingMetadata. The workflow reads that source list for every answer and checks whether your website appears, and which competitor domains appear alongside it.

Each prompt becomes a row in Google Sheets: the question, whether your domain was cited, the exact sources of yours that were used, which competitor domains were cited, and the total number of sources. Because it appends over time, you get a trend of how often AI answers lean on your content. At the end of the run you get one email: “acmeanalytics.com was cited as a source in 2/4 grounded AI answers (50%),” with a table of prompts and a list of the most-cited domains this run.

This is the citation layer of AEO, answer engine optimization. It pairs naturally with the other two checks in the set: the brand-mention tracker (does the AI say your name) and the competitor visibility monitor (how you rank against rivals). New to n8n? Start with how to set up n8n.

Why it beats the default

The default is to have no idea. You publish content, you hope AI answers use it, and you never find out. Checking by hand does not work either: a normal ChatGPT or Gemini answer will not tell you which pages it drew on, because a plain model call answers from memory with no sources at all.

Paid AEO platforms track citations, but they cost a monthly subscription and decide for you which prompts and competitors to watch. This workflow uses grounded search to get the real source list, checks exactly the domains you care about on the exact questions your buyers ask, and writes the history to a sheet you own, for pennies a run. When you publish a new guide, you can watch here whether AI answers start citing it. For more AI workflows you can import, see the best n8n AI agent templates and the full template library.

What you need

  • An n8n instance (Cloud or self-hosted, version 1.0 or newer).
  • A Google Gemini API key with grounding available (free tier includes a daily grounding allowance). Used as an HTTP Header Auth credential with header x-goog-api-key.
  • A Google account for Sheets and a Gmail account for the report.
  • A blank Google Sheet with a header row matching the field names below.
  • Your website domain and a short list of competitor domains.

Time: about 40 minutes from scratch, or under 5 minutes with the template.

Node-by-node list

Seven nodes: a schedule, a config node, one grounded AI call per prompt, a citation reader, and a fork that logs and emails.

Weekly schedule (Mon 7am)
        |
   Prompts & config  (Code: your domain + competitors + prompts)
        |
   Ask Gemini (grounded)  (HTTP: search grounding on)
        |
   Extract citations  (Code: is your domain in the sources?)
        |          |
 Log to Sheets   Build digest
                     |
            Send digest email (Gmail)
  
  1. Weekly schedule (Schedule Trigger) fires every Monday at 7am.
  2. Prompts & config (Code) holds your domain, competitor domains, and prompts.
  3. Ask Gemini (grounded) (HTTP Request) sends each prompt with Google Search grounding enabled.
  4. Extract citations (Code) reads the source list and checks for your domain.
  5. Log to Google Sheets (Google Sheets) appends one row per prompt.
  6. Build digest (Code) rolls the rows into one report with a most-cited-domains list.
  7. Send digest email (Gmail) emails you the report.

Step-by-step build

1. Add the weekly schedule

Add a Schedule Trigger, interval Weeks, every 1 week, day Monday, hour 7. Weekly keeps grounded-search usage tiny while still catching the trend.

2. Set your domain, competitors, and prompts

Add a Code node with your website domain, the competitor domains to watch, and your prompt list. It emits one item per prompt.

const DOMAIN = 'acmeanalytics.com';
const COMPETITOR_DOMAINS = ['datapulse.io', 'insightly.com'];
const PROMPTS = [
  'What are the best analytics tools for a small ecommerce store?',
  'How do I track marketing ROI for a SaaS startup?',
  'What is a good tool for automated weekly sales reports?',
  'How do small teams build a KPI dashboard without engineers?'
];
return PROMPTS.map(p => ({ json: { prompt: p, domain: DOMAIN, competitorDomains: COMPETITOR_DOMAINS } }));
💡

Tip: Use the bare domain (acmeanalytics.com), not the full URL. The check matches that string against every source, so the shorter and more distinctive it is, the cleaner the result.

3. Ask Gemini with grounding

Add an HTTP Request node, method POST. Under Authentication choose Generic Credential Type then Header Auth, with your key stored under the header x-goog-api-key. The body turns grounding on with the google_search tool:

URL:  https://generativelanguage.googleapis.com/v1beta/models/gemini-2.5-flash:generateContent

JSON body:
={{ JSON.stringify({
  contents: [ { parts: [ { text: $('Prompts & config').item.json.prompt } ] } ],
  tools: [ { google_search: {} } ]
}) }}
📌

Note: The tools: [{ google_search: {} }] block is the whole point. Without it Gemini answers from memory and returns no sources, so there is nothing to check.

4. Extract the citations

Add a Code node. It reads the grounded answer’s source list from groundingMetadata.groundingChunks and checks whether your domain, and each competitor domain, appears.

const cfg = $('Prompts & config').item.json;
const domain = String(cfg.domain).toLowerCase();
const competitors = (cfg.competitorDomains || []).map(d => String(d).toLowerCase());

const cand = ($json?.candidates?.[0]) || {};
const chunks = cand.groundingMetadata?.groundingChunks || [];
const sources = chunks.map(c => ({ uri: c.web?.uri || '', title: c.web?.title || '' }));
const blob = s => (s.uri + ' ' + s.title).toLowerCase();

const yourSources = sources.filter(s => blob(s).includes(domain)).map(s => s.title || s.uri);
const compCited = competitors.filter(cd => sources.some(s => blob(s).includes(cd)));
const citedDomains = Array.from(new Set(sources.map(s => s.title).filter(Boolean)));

return [{ json: {
  report_date: new Date().toISOString().slice(0, 10),
  prompt: cfg.prompt,
  your_domain: cfg.domain,
  your_domain_cited: yourSources.length ? 'yes' : 'no',
  your_cited_sources: yourSources.join(' | '),
  competitor_domains_cited: compCited.join(', '),
  total_sources: sources.length,
  all_cited_domains: citedDomains.slice(0, 10).join(', ')
} }];

A single row looks like this:

{
  "report_date": "2026-08-24",
  "prompt": "What are the best analytics tools for a small ecommerce store?",
  "your_domain": "acmeanalytics.com",
  "your_domain_cited": "yes",
  "your_cited_sources": "acmeanalytics.com",
  "competitor_domains_cited": "datapulse.io",
  "total_sources": 6,
  "all_cited_domains": "acmeanalytics.com, g2.com, datapulse.io, reddit.com"
}
💡

Tip: Grounding returns a redirect URL plus a title that is usually the source domain, so the check looks at both fields. If a source shows only a page title, widen your domain string or add your brand name to the match.

5. Log to Sheets and email the report

Add a Google Sheets node (operation Append Row, mapping Map Automatically) with a header row of report_date, prompt, your_domain, your_domain_cited, your_cited_sources, competitor_domains_cited, total_sources, all_cited_domains. Then add a Code node to build the digest and a Gmail node (Email Type HTML) mapping subject and message from it. Save and activate.

Common mistakes

  • Forgetting the grounding tool. Without tools: [{ google_search: {} }] there are no sources to read, and every prompt returns “not cited”.
  • Passing a full URL as your domain. Use the bare domain so it matches both the source URL and the title field.
  • Naming a brand in the prompt. As with the rest of the AEO set, prompts must be neutral buyer questions or the result is rigged.
  • Expecting citations from a non-grounded model. Plain generateContent answers from memory. Only grounded search returns a source list.
  • Mismatched Sheet headers. Automatic mapping needs exact column names, or columns land blank.

Cost at realistic volume

One grounded call per prompt, one Sheets append per prompt, one email per run.

Service Usage per weekly run (8 prompts) Cost
Gemini grounded search 8 grounded calls Free daily allowance, then ~$35 / 1,000 prompts
Google Sheets 8 row appends Free
Gmail 1 email Free
n8n 1 execution / week Free self-hosted; ~4 executions/month on Cloud

At eight prompts a week you are around thirty grounded calls a month, comfortably inside the free allowance for most accounts, or a few cents if you exceed it. The paid tools that track AI citations start around fifty dollars a month.

Get the AI citation monitor template

The guide above is free to follow. If you would rather skip the build, the ready-to-import template drops all seven nodes and every script onto your canvas. Import it, add your Gemini, Google Sheets, and Gmail credentials, set your domain and prompts, and your first citation report can run today. Want it installed and tuned to your market? Our done-for-you service sets it up end to end.

Download the template ($19) →

Instant download · Works on n8n Cloud and self-hosted

Frequently asked questions

What is an AI citation and why does it matter?

When a grounded AI answer pulls from the live web, it lists the sources it drew on. Being one of those sources means the AI is reading and trusting your content, which drives referral traffic and shapes how it describes your space. Getting cited is the AEO equivalent of ranking on page one.

How is this different from tracking brand mentions?

A brand mention is the AI saying your name. A citation is the AI linking to your website as a source it used. You can be mentioned without being cited, and cited without being named. This workflow tracks the citation, which is the one that sends traffic and signals authority.

Why use Gemini with Google Search grounding?

Plain model calls answer from memory and return no sources. Grounding tells Gemini to search the live web and attach the pages it used in groundingMetadata. That source list is exactly what this workflow reads, so grounding is what makes citation tracking possible at all.

Does grounded search cost more than a normal AI call?

Yes, a little. Grounding with Google Search has a free daily allowance, then bills around thirty-five dollars per thousand grounded prompts. A weekly run of six to ten prompts stays inside the free tier or costs pennies a month, far less than a paid AEO tool.

Can I track citations in ChatGPT or Perplexity too?

Yes. Add an HTTP node for OpenAI’s web-search model or Perplexity, both of which return source URLs, and feed their sources into the same Extract citations logic. The Sheets log and digest do not change, so you can widen coverage without rebuilding.

Related guides

n8n competitor AI-visibility monitor (ChatGPT & Gemini)


An n8n competitor AI-visibility monitor answers the question a mention tracker cannot: when a buyer asks ChatGPT or Gemini for a recommendation, do you win, or does a rival get named first? Knowing you appear 40% of the time means little on its own. Knowing you rank third behind two competitors, and that one of them is named first in almost every answer, is something you can act on. This guide builds a free workflow that runs weekly, sends the same buyer questions to both assistants, scores every brand you name, and emails you a ranked leaderboard with mention counts and average position. It takes about 45 minutes to build, or a couple of minutes with the template at the end.

What it does

Each week the workflow sends a set of neutral buyer prompts, the questions people ask before choosing a product like yours, to Google Gemini and OpenAI’s ChatGPT through their official APIs. For every answer it scans for your brand and each competitor you listed, records who was mentioned, and notes the order they appeared in. Being named first in an answer counts for more than being named last, so the workflow tracks position, not just presence.

It then rolls everything into a leaderboard: one row per brand with Gemini mentions, ChatGPT mentions, total mentions, a mention rate across all answer slots, and an average position. The board is sorted so the brand the assistants recommend most sits on top, with average position breaking ties. That snapshot is appended to Google Sheets, so each brand’s standing trends over time, and the same board arrives in your inbox as a table headed by your own rank.

This is the competitive layer of AEO, answer engine optimization. If you only want to know whether your own brand shows up, the simpler brand-mention tracker is the place to start. This monitor is for when you already know you are in the race and want to see the standings. New to n8n? Begin with how to set up n8n.

Why it beats the default

The default competitive check is to open ChatGPT, ask “what is the best tool for X,” eyeball whether you or a rival shows up, and move on. It is a guess, not a measurement. You cannot tell whether a competitor beats you consistently or you just caught a bad answer, and you have no record to compare against next month.

Paid AEO platforms will build a competitor leaderboard, but they cost a monthly subscription, track a prompt list you do not fully control, and keep the history locked in their tool. This workflow ranks exactly the brands you care about, on the exact buyer questions that matter to your market, across both major assistants, for a few cents a run, and writes the history to a sheet you own. Add a competitor, change a prompt, or plug in a third assistant whenever you like. For more AI workflows you can import, see the best n8n AI agent templates and the full template library.

What you need

  • An n8n instance (Cloud or self-hosted, version 1.0 or newer).
  • A Google Gemini API key (free tier is fine to start). Used as an HTTP Header Auth credential with header x-goog-api-key.
  • An OpenAI API key. Used as an HTTP Header Auth credential with header Authorization and value Bearer YOUR_KEY.
  • A Google account for Sheets and a Gmail account for the report.
  • A blank Google Sheet with a header row matching the field names below.

Time: about 45 minutes from scratch, or under 5 minutes with the template.

Node-by-node list

Eight nodes: a schedule, a config node, two AI calls per prompt, a single scorer that builds the leaderboard, and a fork that both logs and emails.

Weekly schedule (Mon 7am)
        |
   Prompts & brands  (Code: you + competitors + prompt list)
        |
    Ask Gemini  ──►  Ask ChatGPT
                          |
                   Build leaderboard  (Code: score + rank every brand)
                       |            |
        Log leaderboard to Sheets   Build email
                                        |
                               Send digest email (Gmail)
  
  1. Weekly schedule (Schedule Trigger) fires every Monday at 7am.
  2. Prompts & brands (Code) holds your brand, competitors, and prompts, one item per prompt.
  3. Ask Gemini (HTTP Request) sends each prompt to the Gemini API.
  4. Ask ChatGPT (HTTP Request) sends the same prompt to the OpenAI API.
  5. Build leaderboard (Code) reads every answer, scores all brands, and outputs one ranked row per brand.
  6. Log leaderboard to Sheets (Google Sheets) appends the snapshot.
  7. Build email (Code) formats the board and highlights your rank.
  8. Send digest email (Gmail) emails you the leaderboard.

Step-by-step build

1. Add the weekly schedule

Add a Schedule Trigger, interval Weeks, every 1 week, day Monday, hour 7. Weekly matches how slowly AI answers shift and keeps API usage tiny.

2. Set your brand, competitors, and prompts

Add a Code node. It emits one item per prompt and carries the full brand list on each item so the scorer can rank everyone.

const YOU = 'Acme Analytics';
const COMPETITORS = ['DataPulse', 'Insightly', 'MetricForge'];
const BRANDS = [YOU, ...COMPETITORS];
const PROMPTS = [
  'What are the best analytics tools for a small ecommerce store?',
  'Which tools help a SaaS startup track marketing ROI?',
  'Recommend affordable business intelligence software for a small team.',
  'What is a good tool for automated weekly sales reports?',
  'Best alternatives to a spreadsheet for tracking KPIs?'
];
return PROMPTS.map(p => ({ json: { prompt: p, brands: BRANDS, you: YOU } }));
💡

Tip: Pick competitors whose names are distinctive words. A brand called “Pulse” will match inside “impulse” and inflate its score; “DataPulse” will not.

3. Ask Gemini

Add an HTTP Request node, method POST. Under Authentication choose Generic Credential Type then Header Auth, and store your key under the header x-goog-api-key. Set the body to JSON:

URL:  https://generativelanguage.googleapis.com/v1beta/models/gemini-2.5-flash:generateContent

JSON body:
={{ JSON.stringify({ contents: [ { parts: [ { text: $('Prompts & brands').item.json.prompt } ] } ] }) }}
📌

Note: Reference $('Prompts & brands').item for the prompt, not $json. After the HTTP call the item becomes the API response, but n8n keeps the original items paired so the reference still resolves.

4. Ask ChatGPT

Add a second HTTP Request node, method POST. Store your OpenAI key under the header Authorization with value Bearer then your key. Body JSON:

URL:  https://api.openai.com/v1/chat/completions

JSON body:
={{ JSON.stringify({ model: 'gpt-4o-mini', messages: [ { role: 'user', content: $('Prompts & brands').item.json.prompt } ] }) }}

5. Build the leaderboard

Add a Code node. It runs once for all items, reads every Gemini and ChatGPT answer, and for each brand counts mentions and averages the order it was named. It outputs one ranked row per brand.

const cfgAll = $('Prompts & brands').all().map(i => i.json);
const gem = $('Ask Gemini').all().map(i => i.json);
const oa = $('Ask ChatGPT').all().map(i => i.json);
const brands = cfgAll[0].brands;
const you = cfgAll[0].you;
const N = cfgAll.length;

const txt = v => (v == null ? '' : String(v));
const geminiText = i => txt(gem[i]?.candidates?.[0]?.content?.parts?.[0]?.text);
const openaiText = i => txt(oa[i]?.choices?.[0]?.message?.content);

const stat = {};
for (const b of brands) stat[b] = { brand: b, gemini_mentions: 0, chatgpt_mentions: 0, pos_sum: 0, pos_count: 0 };

function scoreAnswer(text, assistant) {
  const lower = text.toLowerCase();
  const found = brands
    .map(b => ({ b, idx: lower.indexOf(b.toLowerCase()) }))
    .filter(x => x.idx >= 0)
    .sort((a, b) => a.idx - b.idx);
  found.forEach((x, rank) => {
    if (assistant === 'gemini') stat[x.b].gemini_mentions++;
    else stat[x.b].chatgpt_mentions++;
    stat[x.b].pos_sum += (rank + 1);
    stat[x.b].pos_count++;
  });
}

for (let i = 0; i < N; i++) { scoreAnswer(geminiText(i), 'gemini'); scoreAnswer(openaiText(i), 'chatgpt'); }

const reportDate = new Date().toISOString().slice(0, 10);
const totalSlots = N * 2;
const rows = brands.map(b => {
  const s = stat[b];
  const total = s.gemini_mentions + s.chatgpt_mentions;
  return {
    report_date: reportDate, brand: b, is_you: b === you ? 'yes' : 'no',
    gemini_mentions: s.gemini_mentions, chatgpt_mentions: s.chatgpt_mentions,
    total_mentions: total, mention_rate_pct: Math.round((total / totalSlots) * 100),
    avg_position: s.pos_count ? Math.round((s.pos_sum / s.pos_count) * 10) / 10 : ''
  };
});
rows.sort((a, b) => b.total_mentions - a.total_mentions || ((a.avg_position === '' ? 99 : a.avg_position) - (b.avg_position === '' ? 99 : b.avg_position)));
return rows.map(r => ({ json: r }));

A leaderboard row looks like this:

{
  "report_date": "2026-08-24",
  "brand": "DataPulse",
  "is_you": "no",
  "gemini_mentions": 4,
  "chatgpt_mentions": 5,
  "total_mentions": 9,
  "mention_rate_pct": 90,
  "avg_position": 1.3
}

6. Log to Google Sheets and email the board

Add a Google Sheets node (operation Append Row, mapping Map Automatically) with a header row of report_date, brand, is_you, gemini_mentions, chatgpt_mentions, total_mentions, mention_rate_pct, avg_position. Then add a Code node to format the board and a Gmail node (Email Type HTML) mapping the subject and message from it. The email leads with your rank: “You rank #3 of 4 with a 50% mention rate.”

Save and activate. Every Monday you get a standings table you can actually plan against.

Common mistakes

  • Naming a brand in the prompt. It rigs the result. Prompts must be neutral buyer questions.
  • Short or generic brand names. They match inside other words and inflate scores. Track full, distinctive names and tighten the match to whole words if needed.
  • Reading $json for Gemini in the scorer. After the ChatGPT node, $json is the OpenAI item. Pull both answer sets with $('Ask Gemini').all() and $('Ask ChatGPT').all().
  • Comparing runs with different prompt lists. Change the prompts and the trend breaks. Lock a core set and only add to it deliberately.
  • Mismatched Sheet headers. Automatic mapping needs exact column names, or columns land blank.

Cost at realistic volume

Two API calls per prompt, one Sheets append per brand, one email per run.

Service Usage per weekly run (10 prompts, 4 brands) Cost
Gemini API (gemini-2.5-flash) 10 calls Free tier covers it
OpenAI API (gpt-4o-mini) 10 calls ~$0.01 / run
Google Sheets 4 row appends Free
Gmail 1 email Free
n8n 1 execution / week Free self-hosted; ~4 executions/month on Cloud

A competitive AI-visibility leaderboard for a few cents a month. The paid platforms that produce the same board start around fifty dollars a month.

Get the competitor AI-visibility monitor template

The guide above is free to follow. If you would rather skip the build, the ready-to-import template drops all eight nodes and every script onto your canvas. Import it, add your Gemini, OpenAI, Google Sheets, and Gmail credentials, list your competitors and prompts, and your first leaderboard can run today. Want it installed and tuned to your market? Our done-for-you service sets it up end to end.

Download the template ($19) →

Instant download · Works on n8n Cloud and self-hosted

Frequently asked questions

How is this different from just tracking whether my brand is mentioned?

A mention tracker answers yes or no for your brand alone. A competitor monitor ranks you against named rivals across the same questions, so you see who wins the recommendation, by how much, and who gets named first. It turns a single data point into a leaderboard you can move up.

What does average position measure?

Within each AI answer, brands are ranked by the order they are named. Average position is the mean of those ranks across every answer where the brand appears. A lower number means the assistant tends to name that brand earlier, which usually means it is the stronger default recommendation.

How many competitors can I track?

As many as you like. Add them to the COMPETITORS list in the config node and they are scored automatically. Five to eight is a practical range; beyond that the leaderboard gets noisy and some brand names start to collide with common words in the answers.

Does it use the real ChatGPT and Gemini?

It calls the official OpenAI and Google Gemini APIs, which run the same models behind the chat apps and are stable to parse. Scraping the chat websites is against their terms and breaks often, so the API is the correct and reliable route for automation.

What prompts give the most useful ranking?

Neutral category questions a buyer would ask before choosing: best tool for X, affordable software for Y, alternatives to a spreadsheet. Never name any brand in the prompt. The whole point is to see which brands the AI raises on its own when asked a fair, open question.

Related guides

Track brand mentions in ChatGPT and Gemini with n8n


To track brand mentions in ChatGPT and Gemini with n8n, you need a workflow that asks each AI the questions your buyers ask, then checks whether your name comes up in the answer. Search is no longer the only front door: people ask an assistant “what is the best tool for X” and act on the shortlist it gives them. If that shortlist names your competitors and not you, you are losing deals in a place you cannot see. This guide builds a free workflow that runs weekly, sends a set of buyer-style prompts to both Gemini and ChatGPT, records whether your brand and your competitors are mentioned, logs every result to Google Sheets, and emails you a share-of-voice report. It takes about 40 minutes to build, or a couple of minutes with the template at the end.

What it does

Once a week the workflow runs a list of prompts you control, the kind a prospect would type before choosing a product like yours. It sends each prompt to Google Gemini and to OpenAI’s ChatGPT through their official APIs, reads both answers, and marks whether your brand name appears in each one. It does the same check for a list of competitors, so you see not just whether you showed up but who showed up instead.

Every prompt becomes a row in Google Sheets with the date, the question, a yes or no for each assistant, and which competitors were named. Because it appends rather than overwrites, the sheet becomes a visibility trend you can chart over months. At the end of the run you get one email: “Acme Analytics was mentioned in 3/4 Gemini answers (75%) and 1/4 ChatGPT answers (25%),” with the full table underneath.

This is the measurement layer of AEO, answer engine optimization, sometimes called generative engine optimization. You cannot improve what you do not measure, and until now brand visibility inside AI answers has been a blind spot. If you are new to n8n, start with how to set up n8n, then come back here.

Why it beats the default

The default is to open ChatGPT once, type a question, see that you are not mentioned, feel bad, and close the tab. That is a spot check, not a measurement. It is not repeatable, it is not logged, and it tells you nothing about whether things are getting better or worse.

A handful of paid AEO monitoring tools now exist, but they charge a monthly subscription, track a fixed prompt list, and keep the data inside their dashboard. This workflow costs cents to run, tracks exactly the prompts your buyers use, checks both major assistants in one pass, and writes to a sheet you own. You can add a provider, change the prompts, or widen the competitor list whenever you like, because the logic lives in your instance, not behind someone else’s paywall. For more ready-made AI workflows, see the best n8n AI agent templates and the full template library.

What you need

  • An n8n instance (Cloud or self-hosted, version 1.0 or newer).
  • A Google Gemini API key (the free tier is enough to start). Used as an HTTP Header Auth credential with header x-goog-api-key.
  • An OpenAI API key. Used as an HTTP Header Auth credential with header Authorization and value Bearer YOUR_KEY.
  • A Google account for Sheets and a Gmail account for the report email.
  • A blank Google Sheet with a header row matching the field names below.

Time: about 40 minutes from scratch, or under 5 minutes if you import the template and add your credentials.

Node-by-node list

Eight nodes: a schedule, a config node, two AI calls per prompt, a checker, and a fork that both logs and emails.

Weekly schedule (Mon 7am)
        |
   Prompts & config  (Code: your brand + competitors + prompt list)
        |
    Ask Gemini  ──►  Ask ChatGPT
                          |
                    Check mentions  (Code: does the brand appear?)
                       |            |
        Log to Google Sheets    Build digest
                                     |
                            Send digest email (Gmail)
  
  1. Weekly schedule (Schedule Trigger) fires every Monday at 7am.
  2. Prompts & config (Code) holds your brand, competitors, and prompt list, one item per prompt.
  3. Ask Gemini (HTTP Request) sends each prompt to the Gemini API.
  4. Ask ChatGPT (HTTP Request) sends the same prompt to the OpenAI API.
  5. Check mentions (Code) reads both answers and records the hits.
  6. Log to Google Sheets (Google Sheets) appends one row per prompt.
  7. Build digest (Code) rolls the rows into one summary.
  8. Send digest email (Gmail) emails you the report.

Step-by-step build

1. Add the weekly schedule

Add a Schedule Trigger, interval Weeks, every 1 week, day Monday, hour 7. Weekly is the right cadence: AI answers drift slowly, and a weekly reading is enough to catch a trend without burning API calls.

2. Set your brand, competitors, and prompts

Add a Code node. It emits one item per prompt so the rest of the workflow processes each question independently. Edit the three lists to match your business.

const BRAND = 'Acme Analytics';
const COMPETITORS = ['DataPulse', 'Insightly'];
const PROMPTS = [
  'What are the best analytics tools for a small ecommerce store?',
  'Which tools help a SaaS startup track marketing ROI?',
  'Recommend affordable business intelligence software for a small team.',
  'What is a good tool for automated weekly sales reports?'
];
return PROMPTS.map(p => ({ json: { prompt: p, brand: BRAND, competitors: COMPETITORS } }));
💡

Tip: Never put your brand name in a prompt. The point is to see whether the AI raises you unprompted. “Best CRM for real estate” is a good prompt; “Is Acme the best CRM” is not.

3. Ask Gemini

Add an HTTP Request node. Set method POST and URL to the Gemini endpoint. Under Authentication choose Generic Credential Type, then Header Auth, and create a credential with name x-goog-api-key and your Gemini key as the value. Set the body to JSON and paste this expression:

URL:  https://generativelanguage.googleapis.com/v1beta/models/gemini-2.5-flash:generateContent

JSON body:
={{ JSON.stringify({ contents: [ { parts: [ { text: $('Prompts & config').item.json.prompt } ] } ] }) }}
📌

Note: Referencing $('Prompts & config').item instead of $json keeps the original prompt available even after the HTTP node replaces the item with the API response. n8n pairs the items automatically.

4. Ask ChatGPT

Add a second HTTP Request node, method POST, pointing at the OpenAI endpoint. Create a Header Auth credential with name Authorization and value Bearer followed by your OpenAI key. Body JSON:

URL:  https://api.openai.com/v1/chat/completions

JSON body:
={{ JSON.stringify({ model: 'gpt-4o-mini', messages: [ { role: 'user', content: $('Prompts & config').item.json.prompt } ] }) }}

5. Check for mentions

Add a Code node. It reads both answers, checks whether the brand and each competitor appear, and outputs one clean row per prompt.

const cfg = $('Prompts & config').item.json;
const brand = cfg.brand;
const competitors = cfg.competitors || [];

const txt = v => (v == null ? '' : String(v));
const gem = $('Ask Gemini').item.json;
const geminiText = txt(gem?.candidates?.[0]?.content?.parts?.[0]?.text);
const openaiText = txt($json?.choices?.[0]?.message?.content);

const has = (hay, needle) => hay.toLowerCase().includes(String(needle).toLowerCase());

return [{ json: {
  report_date: new Date().toISOString().slice(0, 10),
  prompt: cfg.prompt,
  brand: brand,
  gemini_mentioned: has(geminiText, brand) ? 'yes' : 'no',
  chatgpt_mentioned: has(openaiText, brand) ? 'yes' : 'no',
  competitors_in_gemini: competitors.filter(c => has(geminiText, c)).join(', '),
  competitors_in_chatgpt: competitors.filter(c => has(openaiText, c)).join(', '),
  gemini_excerpt: geminiText.slice(0, 300),
  chatgpt_excerpt: openaiText.slice(0, 300)
} }];

A single row looks like this:

{
  "report_date": "2026-08-24",
  "prompt": "What are the best analytics tools for a small ecommerce store?",
  "brand": "Acme Analytics",
  "gemini_mentioned": "yes",
  "chatgpt_mentioned": "no",
  "competitors_in_gemini": "DataPulse",
  "competitors_in_chatgpt": "Insightly, DataPulse"
}

6. Log to Google Sheets

Add a Google Sheets node, operation Append Row. Pick your document and sheet and set mapping to Map Automatically. Your header row should match the field names: report_date, prompt, brand, gemini_mentioned, chatgpt_mentioned, competitors_in_gemini, competitors_in_chatgpt, gemini_excerpt, chatgpt_excerpt.

7. Build the digest and email it

Add a Code node that collapses every row into one summary item, then a Gmail node to send it. Set the Gmail node’s Email Type to HTML and map subject and message from the digest.

const items = $input.all().map(i => i.json);
if (items.length === 0) return [];
const total = items.length;
const gemHits = items.filter(r => r.gemini_mentioned === 'yes').length;
const oaHits = items.filter(r => r.chatgpt_mentioned === 'yes').length;
const pct = n => Math.round((n / total) * 100);
// ... builds an HTML table + subject line, returns one item
return [{ json: { subject: 'AI visibility: ' + pct(gemHits) + '% Gemini / ' + pct(oaHits) + '% ChatGPT', html: html } }];

Save and activate. You now have a repeatable, logged reading of your brand’s visibility inside the two assistants your buyers use most.

Common mistakes

  • Naming your brand in the prompt. That guarantees a mention and measures nothing. Prompts must be neutral buyer questions.
  • Reading $json in the Check node for the Gemini answer. After the ChatGPT call, $json is the OpenAI response. Pull Gemini’s text with $('Ask Gemini').item.
  • Wrong header for the API key. Gemini wants x-goog-api-key; OpenAI wants Authorization: Bearer. Swapping them returns a 401.
  • Sheet headers that do not match. Automatic mapping keys off exact column names. A header of Gemini will not catch the field gemini_mentioned.
  • Substring false positives. A short brand name can match inside another word. If your brand is two or three letters, tighten the has() check to match whole words.

Cost at realistic volume

The workflow makes two API calls per prompt, plus one Sheets append and one email per run.

Service Usage per weekly run (15 prompts) Cost
Gemini API (gemini-2.5-flash) 15 calls Free tier covers it
OpenAI API (gpt-4o-mini) 15 calls ~$0.01 / run
Google Sheets 15 row appends Free
Gmail 1 email Free
n8n 1 execution / week Free self-hosted; ~4 executions/month on Cloud

Call it a few cents a month for a real, trended view of your AI visibility. The paid tools that do this start around thirty dollars a month for a fixed prompt list.

Get the AI visibility tracker template

The guide above is free to follow. If you would rather skip the build, the ready-to-import template drops all eight nodes and every script onto your canvas. Import it, add your Gemini, OpenAI, Google Sheets, and Gmail credentials, edit your brand and prompts, and your first report can run today. Want it installed and tuned to your market? Our done-for-you service sets it up end to end.

Download the template ($19) →

Instant download · Works on n8n Cloud and self-hosted

Frequently asked questions

Why track brand mentions in ChatGPT and Gemini at all?

More buyers now ask an AI assistant for recommendations before they ever reach Google. If ChatGPT and Gemini name your competitors and not you, you lose the sale before the research starts. This workflow turns that invisible risk into a number you can watch and improve.

Does this use the real ChatGPT and Gemini, or the public websites?

It calls the official OpenAI and Google Gemini APIs, not the chat websites. The API answers come from the same underlying models, they are stable to parse, and scripting them is allowed. Scraping the chat sites is against their terms and breaks constantly, so the API is the correct route.

How much does it cost to run each week?

Gemini has a free tier that covers a small prompt set, and gpt-4o-mini costs a fraction of a cent per prompt. A weekly run of ten to twenty prompts across both providers costs a few cents a month. The Google Sheets and Gmail steps are free.

Can I add Perplexity or Claude to the same report?

Yes. Duplicate the Ask Gemini node, point it at the other provider’s API, and add its result to the Check mentions node. The rest of the workflow does not change, so you can grow from two assistants to four without rebuilding anything.

What prompts should I track?

Use the questions a buyer would actually type before choosing a product like yours: best tool for X, affordable software for Y, alternatives to a competitor. Avoid prompts that name your brand, because the goal is to see whether the AI raises you on its own.

Related guides

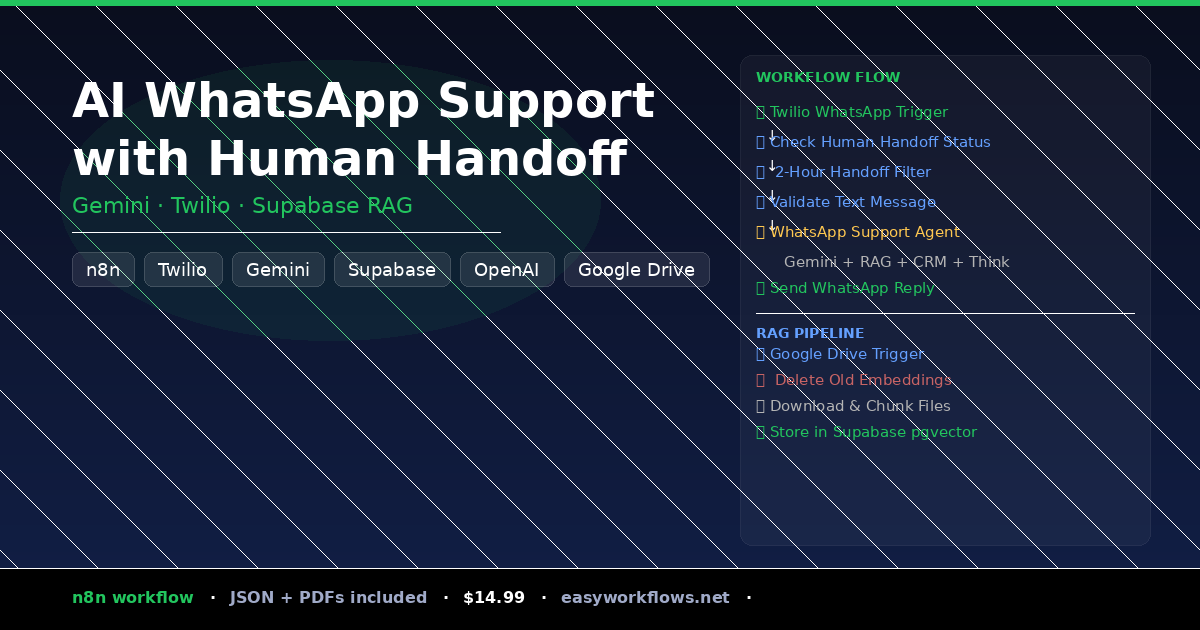
How to Build an AI Document Chatbot with n8n, Google Drive and Supabase

New to n8n? Start with our step-by-step setup guide, then come back to build this workflow.

You’ve got dozens of PDFs, reports, and spreadsheets scattered across Google Drive. Finding that one specific number or policy buried on page 47? That’s where your afternoon goes.

What if your documents could talk? Imagine asking your chatbot “What was our Q3 revenue projection?” and getting an instant, accurate answer pulled from your actual files, not a hallucination. That’s the power of RAG (Retrieval Augmented Generation).

In this guide, we’re building exactly that: an AI document chatbot that automatically processes everything you upload to Google Drive, makes it searchable, and lets you chat with it using natural language. We’ll use n8n to orchestrate the whole pipeline, Google Drive for storage, Google Gemini to enhance your content, OpenAI for embeddings and chat, and Supabase as our vector database.

By the end, you’ll have a workflow that doesn’t just read documents, it understands them contextually and retrieves the most relevant information on demand.

What You’ll Build

This workflow has two halves that work together seamlessly:

The Document Processing Pipeline watches your Google Drive folder, automatically grabs new files (PDFs, CSVs, Google Docs), extracts the text, enhances it with AI smarts, splits it into searchable chunks, generates vector embeddings, and stores everything in a Supabase database.

The Chat Interface is where users interact. When someone sends a message, an AI agent searches your vector database for the most relevant chunks, reads them in context, and generates an intelligent answer grounded in your actual documents.

The magic here is that the chatbot doesn’t just guess. It retrieves and reasons over your real data. No more “I don’t have that information.” Your documents become your knowledge base.

How It Works: High-Level Architecture

┌─────────────────────────────────────────────────────────────────┐
│                    Document Processing Pipeline                 │
├─────────────────────────────────────────────────────────────────┤
│                                                                   │
│  Google Drive      Extract      AI Enhancement    Vector Store   │
│   Folder          Text               │              (Supabase)   │
│      │               │         Generate:               │         │
│      │               │         • Metadata       • Embeddings     │
│      │               │         • Context        • Chunks         │
│      └──────────────┬┴────────────┬────────────────┤             │
│                     │             │                │             │
│            (Monitor every minute)                  │             │
│                                                    └─────────┐   │
│                                                              │   │
├──────────────────────────────────────────────────────────────┼──┤
│                   Chat Interface                             │  │
├──────────────────────────────────────────────────────────────┼──┤
│                                                              │  │
│  User Message     Search      Retrieve      Generate        │  │
│      │            Vector DB   Context       Answer           │  │
│      │               │            │            │             │  │
│      └───────────────┼────────────┼────────────┤             │  │
│                      │            │            │             │  │
│            (Powered by OpenAI GPT-4o-mini) ←──┘             │  │
│                                               │             │  │
│                            Sourced from Supabase────────────┘  │
│                                                                   │
└─────────────────────────────────────────────────────────────────┘

What You’ll Need

Before we start building, gather these:

  • n8n account: cloud or self-hosted, either works
  • Google account: for Google Drive and Google Gemini API access
  • OpenAI API key: for embeddings and the GPT-4o-mini chat model
  • Supabase account: free tier is fine; you’ll create a PostgreSQL database with the pgvector extension
  • A Google Drive folder: dedicated to documents you want indexed
  • Sample documents: PDFs, CSVs, or Google Docs to test with

Estimated setup time: 15 to 20 minutes. The workflow itself is provided as a template you can import directly.

Part 1: Document Processing Pipeline

This is the intake system. Every minute, it checks for new files and prepares them for retrieval.

1 Google Drive Trigger

The entry point. Configure this node to:

  • Connect your Google account via OAuth2
  • Select the Google Drive folder where you’ll upload documents
  • Set the poll frequency to every 1 minute (or adjust to your needs)

This trigger fires whenever n8n detects new or modified files in that folder. You can filter by file type if you want (e.g., only PDFs and CSVs).

2 Loop Over Items

Since Google Drive might return multiple files, we process them one by one. This node iterates through the list so each file gets its own execution path through the pipeline.

3 Set File ID

A simple expression node that extracts and stores the Google Drive file ID. We’ll use this later to track which document a chunk came from. Use an expression like: $json.fileId

4 Download File

Downloads the actual file from Google Drive. Important: Google Docs are automatically converted to PDF during download, so you get consistent text extraction across all document types.

5 Switch Node (MIME Type Router)

Routes the file to the right text extraction method based on its type:

  • If MIME type is application/pdf → send to PDF extractor
  • If MIME type is text/csv → send to CSV extractor

This branching logic ensures each file type is handled with the right tool.

6 Extract from PDF / Extract from CSV

Two parallel nodes (one for each file type) that pull raw text:

  • PDF extraction: Use n8n’s built-in PDF node or a code snippet to extract text, preserving paragraph structure where possible
  • CSV extraction: Parse the CSV, convert rows to readable text (e.g., “Row 1: Name=Jennifer Chen, Department=Marketing, Salary=92000”)

Both outputs feed into the next stage as plain text.

💡

Rough PDFs or image-heavy documents? Consider adding an OCR step here using services like Google Vision API. It adds latency but ensures no text is missed. Check our template marketplace for OCR-enhanced variants.

7 Document Data (JSON Wrapper)

Wraps the extracted text in a structured JSON object:

{
  "text": "[extracted text here]",
  "file_id": "[Google Drive ID]",
  "file_name": "[original filename]",
  "mime_type": "[pdf or csv]"
}

This structure carries metadata through the pipeline, so we always know where each chunk originated.

8 Create Metadata (Google Gemini)

Before we split text into chunks, we generate high-level metadata using Google Gemini. Send the full document text to Gemini with a prompt like:

“Read this document and provide: (1) A concise title (5 to 10 words), (2) A brief description (1 to 2 sentences) explaining what this document contains and who should read it. Output as JSON: {title, description}”

Gemini returns structured metadata that will be attached to every chunk from this document. This is crucial: when the chatbot retrieves chunks, it shows the user which document they came from and why it’s relevant.

9 Split Into Chunks (Code Node)

Raw documents are too large to process as embeddings. This node intelligently splits text into 1000-character chunks with 200-character overlap, respecting sentence and paragraph boundaries:

// Simplified chunking logic (pseudocode)
const chunkSize = 1000;
const overlapSize = 200;
let chunks = [];
let currentChunk = '';

// Split on sentences/paragraphs first
const sentences = text.split(/(?<=[.!?])\s+/);

for (let sentence of sentences) {
  if ((currentChunk + sentence).length > chunkSize) {
    chunks.push(currentChunk.trim());
    currentChunk = currentChunk.slice(-overlapSize) + sentence;
  } else {
    currentChunk += ' ' + sentence;
  }
}
if (currentChunk) chunks.push(currentChunk.trim());

return chunks;

This ensures that no information is lost at chunk boundaries, and related concepts stay together.

10 Split Out

Converts the chunks array into separate items so each chunk flows through its own execution. If a document produces 50 chunks, this creates 50 parallel execution paths.

11 Limit (Optional)

A safety valve: limits processing to the first 20 chunks per document. Set this based on your OpenAI quota and cost tolerance. You can remove it for unlimited processing.

12 Process Context (Google Gemini)

Each chunk is sent to Gemini for contextual enhancement. Prompt:

“Here is an excerpt from a larger document. Enhance this excerpt with additional context that would help someone retrieve and understand it later. Add brief background, define jargon, and clarify pronouns. Keep it to 1 to 2 sentences. Return the enhanced excerpt.”

Example: If a chunk says “Q3 revenue up 15%”, Gemini might enhance it to “Q3 2025 revenue increased 15% compared to Q2 2025, reaching $4.2M.” Now when the chatbot retrieves this chunk for a question like “What was our revenue trend?”, it has full context.

13 Summarize (Concatenate)

Combines the enhanced chunks back into a single string, separated by a delimiter (e.g., \n---\n). This serves as the final text to embed. The structure is:

[Enhanced Chunk 1]
---
[Enhanced Chunk 2]
---
[Enhanced Chunk 3]

14 Add Data to Supabase Vector Store

The final step: store everything in Supabase. This node does three things:

  1. Generates OpenAI embeddings for each chunk (using text-embedding-3-small model)
  2. Prepares metadata (file_id, title, description, chunk index)
  3. Stores in Supabase with the embedding vector, content, and metadata

The node uses Supabase’s built-in vector support. Each row in your documents table looks like:

  • content: The enhanced chunk text
  • embedding: The 1536-dimensional vector from OpenAI
  • metadata: JSON with file_id, title, description, chunk_index

Once this completes, your document is fully indexed and searchable.

Part 2: Chat Interface

Now users can ask questions and get answers grounded in their documents.

1 When Chat Message Received

This is n8n’s chat trigger. Users send messages through the n8n UI (or via webhook if you embed it elsewhere), and each message fires this trigger. The input includes the user’s question and conversation history.

2 AI Agent (OpenAI)

The brain of the system. Configure an n8n AI Agent node with:

Model: GPT-4o-mini (fast, cost-effective, smart enough for RAG retrieval)

System Prompt:

“You are an internal company knowledge assistant. Your job is to answer questions about company documents. Always search the Vector Database first using the provided tool. Retrieve the most relevant document excerpts. Ground your answer in what you found. Never guess or make up information. If you cannot find relevant information, say so honestly.”

Memory: Enable Simple Memory with a 10-message limit so the chatbot remembers recent context within a conversation.

Tools: Attach the Supabase Vector Store as a tool. This gives the agent the ability to search for relevant chunks when answering a question.

When the user asks “What’s our return policy?”, the agent:

  1. Takes the question
  2. Calls the Vector Store tool with an embedding of the question
  3. Retrieves the top 20 most similar chunks
  4. Reads those chunks
  5. Generates a coherent answer citing the relevant sections

This is RAG in action: retrieval + augmented generation.

The Data Structure: Supabase Setup

Your vector database needs the right schema. In Supabase, run this SQL:

-- Enable pgvector extension
CREATE EXTENSION IF NOT EXISTS vector;

-- Create documents table
CREATE TABLE public.documents (
  id bigserial PRIMARY KEY,
  content text NOT NULL,
  metadata jsonb,
  embedding vector(1536),
  created_at timestamp with time zone DEFAULT now()
);

-- Create an index for faster vector searches
CREATE INDEX documents_embedding_idx
  ON documents
  USING ivfflat (embedding vector_cosine_ops)
  WITH (lists = 100);

-- Create an index on metadata for filtering
CREATE INDEX documents_metadata_idx
  ON documents
  USING GIN (metadata);

Explanation:

  • content: The chunk text itself
  • metadata: JSONB storing file_id, title, description, chunk_index
  • embedding: The 1536-dimensional vector from OpenAI’s embedding model
  • The ivfflat index speeds up similarity searches across millions of chunks

Full System Flow Diagram

START
  │
  ├─► Google Drive Trigger (every 1 min)
  │     │
  │     ├─► Loop Over Items
  │     │     │
  │     │     ├─► Extract File ID
  │     │     │
  │     │     ├─► Download File
  │     │     │
  │     │     ├─► Switch by MIME Type
  │     │     │     │
  │     │     │     ├─► PDF Branch
  │     │     │     │     ├─► Extract PDF Text
  │     │     │     │     └─► Wrap in JSON
  │     │     │     │
  │     │     │     └─► CSV Branch
  │     │     │           ├─► Parse CSV
  │     │     │           └─► Wrap in JSON
  │     │     │
  │     │     ├─► Create Metadata (Gemini)
  │     │     │     └─► Store title + description
  │     │     │
  │     │     ├─► Split into 1000-char Chunks
  │     │     │
  │     │     ├─► Split Out (iterate chunks)
  │     │     │
  │     │     ├─► Limit to 20 chunks
  │     │     │
  │     │     ├─► Process Context (Gemini)
  │     │     │     └─► Enhance each chunk
  │     │     │
  │     │     ├─► Summarize (concatenate)
  │     │     │
  │     │     └─► Add to Supabase
  │     │           ├─► Generate Embedding (OpenAI)
  │     │           └─► Store in Vector DB
  │     │
  │     └─► [Document Indexed & Searchable]
  │
  └─► Chat Interface
        │
        ├─► When Chat Message Received
        │     │
        │     └─► AI Agent (GPT-4o-mini)
        │           │
        │           ├─► Embed Question (OpenAI)
        │           │
        │           ├─► Search Supabase Vector Store
        │           │     └─► Retrieve top 20 chunks
        │           │
        │           └─► Generate Answer
        │                 └─► Return to User
        │
        └─► [Chat Interface Ready]

Testing Your Workflow

Once deployed, test it end-to-end:

  1. Upload a test document to your Google Drive folder. A PDF with company policies works great. You should see the Google Drive trigger fire within 1 minute.
  2. Monitor the workflow execution in n8n. Watch the logs as your document flows through extraction, chunking, enhancement, and embedding.
  3. Verify in Supabase. Query your documents table: SELECT COUNT(*) FROM documents; You should see rows for each chunk.
  4. Test the chat interface. Click the chat icon in n8n and ask a question about your document. For example: “What is the vacation policy?” The chatbot should retrieve relevant chunks and answer from your actual document.
  5. Refine as needed. If answers aren’t specific enough, adjust the context enhancement prompt in Step 12. If too many irrelevant chunks appear, experiment with the chunk size or overlap in Step 9.

A successful test: You ask a specific question (like “Who is responsible for budget approvals?”) and the chatbot cites the exact section of the document it found the answer in.

Frequently Asked Questions

How long does it take to index a new document?

Depends on document size. A typical 20-page PDF takes 30 to 90 seconds: extraction (5s), enhancement (20 to 60s), embedding (5 to 30s), and Supabase storage (5s). Large datasets benefit from batching and optimizing your chunk size.

What happens if I ask the chatbot about something not in my documents?

The AI agent is configured to search the Vector Database first. If no relevant chunks are retrieved, it will respond honestly: “I couldn’t find information about that in the available documents.” No hallucinations. That’s the RAG advantage.

Can I use a different LLM instead of OpenAI?

Yes. n8n supports Anthropic Claude, Google Gemini, and others. For embeddings, you’d need a provider with embedding endpoints (OpenAI, Cohere, or HuggingFace). Swap the model and API keys in the configuration. The workflow structure stays the same.

What’s the cost to run this workflow?

Rough estimates per 100 documents: Google Drive API (~$0, free tier is generous), Google Gemini API (metadata + context: ~$2 to $5), OpenAI embeddings (~$0.02 per document), GPT-4o-mini chat (~$0.015 per conversation, highly variable), Supabase hosting ($0 on free tier, $25/mo for production). Your biggest variable is chat usage and document volume.

Can I delete or update documents in the vector store?

Absolutely. Add a separate n8n workflow with a Supabase trigger that listens for deleted files in Google Drive. When a file is deleted, remove all chunks with matching file_id from the vector store. Same for updates: re-process the document and insert fresh chunks, optionally deleting old ones.

How many documents can the system handle?

Supabase’s free tier supports millions of vectors. The bottleneck is API rate limits: Google’s quota (varies), OpenAI embeddings (up to 3,500 requests/min on paid accounts), and Gemini rate limits. For enterprise scale, contact your API providers for higher quotas.

What’s Next?

You now have a functioning RAG chatbot. Here are natural next steps:

  • Deploy the chat interface publicly: Embed the n8n chat widget on a website or expose it via a webhook so external users can query your documents.
  • Add document filtering: Modify the Vector Store search to filter by department, date range, or document type. Useful if different teams have different documents.
  • Implement multi-language support: Use translation APIs to process documents in French, Spanish, German, etc. The embeddings and chat adapt automatically.
  • Create document analytics: Track which documents get queried most, what questions come up repeatedly, and use that to improve your knowledge base organization.
  • Integrate with Slack or Teams: Instead of a web chat, let employees query documents directly from Slack. n8n webhooks make this straightforward.
  • Add feedback loops: Let users rate chatbot answers (“Was this helpful?”). Log feedback to a table and use it to retrain or improve your prompts.

Ready to Deploy Your RAG Chatbot?

The complete, production-ready n8n workflow template is available right now. Import it directly into your n8n instance, configure your API keys, and start indexing documents in minutes.

Get the Template

One-click import. Full documentation included. Free to modify and extend.

Summary

You now understand the architecture of an enterprise-grade document chatbot. The two-part workflow, document processing and chat interface, works together to create a system that knows your documents intimately and answers questions with precision.

The key innovations:

  • Intelligent chunking preserves context
  • Gemini enhancement adds semantic richness
  • Vector embeddings enable semantic search (not keyword search)
  • RAG prevents hallucinations by grounding answers in actual content
  • Metadata tracking ensures users know where answers come from

Build this workflow, test it with your own documents, and watch it transform how your team accesses information. Stop searching pages manually. Start asking.

ai-chatbot
rag
n8n
google-drive
supabase
openai
vector-database
automation

How to Build an AI Self-Healing Engine for n8n (Auto-Fix Failing Workflows with Azure OpenAI)

New to n8n? Start with our step-by-step setup guide, then come back to build this workflow.

Every n8n user knows the feeling: you check your automations in the morning and find three workflows sitting in failed state. One timed out, one hit a bad API response, one has a broken parameter. Now you’re spending an hour debugging instead of building. What if your n8n instance could diagnose and fix those failures itself, while you slept?

That’s exactly what this workflow does. It’s a global AI-powered error handler that hooks into n8n’s built-in error trigger, fetches the failing workflow’s full JSON, hands it to Azure OpenAI GPT-4o, and either retries the execution automatically or patches the broken parameter, then posts the result to Slack. No manual debugging, no stale failures, no wasted morning.

💡 Prefer to skip the setup? Grab the ready-made template and have your self-healing engine running in under 15 minutes.

What You’ll Build

  1. A global error listener: n8n’s Error Trigger fires the moment any workflow in your instance fails, passing you the full execution context.
  2. A self-loop guard: A Filter node prevents the engine from accidentally triggering itself if it ever fails.
  3. An AI diagnostics layer: Azure OpenAI GPT-4o reads the error message, the failed node name, and the entire workflow JSON, then decides: is this a temporary network hiccup (RETRY) or a fixable logic error (FIX)?
  4. Automatic repair: For RETRY cases, the engine waits one minute and re-runs the failed execution. For FIX cases, it patches the broken parameter directly in the workflow JSON and pushes the update via the n8n API.
  5. Slack alerts for everything: You get a Slack message for every auto-fix applied, every auto-retry queued, and every error that needs a human to look at it.

How It Works: The Big Picture

+—————————————————————————+
| AI SELF-HEALING ENGINE |
| |
| [On Workflow Error] -> [Filter: Ignore Self] -> [Get Workflow JSON] |
| | |
| [Diagnose Error (GPT-4o)] |
| +- AI Model + + Output Schema -+ |
| | |
| [Determine Action] |
| / | \ |
| RETRY FIX MANUAL |
| | | | |
| [Cool Down] [Generate [Notify Manual |
| | Patch JSON] Fix (Slack)] |
| [Retry [Update |
| Execution] Workflow] |
| [Notify Success (Slack)] |
+—————————————————————————+

What You’ll Need

  • n8n (self-hosted or cloud): access to Settings → API for an API key, and Settings → Variables to store it
  • Azure OpenAI account: with a GPT-4o deployment active (GPT-4 Turbo works too)
  • Slack workspace: with a channel designated for automation alerts
  • Build time from scratch: ~60 minutes | With template: ~15 minutes

Step-by-Step Build

Step 1: On Workflow Error (Error Trigger)

This is n8n’s built-in errorTrigger node, nothing to configure. It fires whenever any workflow encounters an unhandled error and passes the full execution context:

{
  "workflow": {
    "id": "a7b3c9d1e2f4",
    "name": "Daily Shopify Order Sync"
  },
  "execution": {
    "id": "exec_88221",
    "lastNodeExecuted": "Send to Google Sheets",
    "error": {
      "message": "The caller does not have permission to execute the requested operation."
    }
  }
}
Tip: After this workflow is live, go into each of your other workflows’ Settings and set Error Workflow to this engine. That’s how n8n routes failures here.

Step 2: Filter: Ignore Self

Compares $json.workflow.id against $workflow.id. Only passes items where the IDs differ, i.e., the failing workflow is not this engine itself. Without this, a failure in the engine would trigger an infinite loop.

Step 3: Get Workflow JSON (HTTP Request)

Fetches the full workflow definition via the n8n API so GPT-4o can read its structure.

Field Value
Method GET
URL {{ $vars.N8N_BASE_URL }}/api/v1/workflows/{{ $json.workflow.id }}
Header: X-N8N-API-KEY {{ $vars.N8N_API_KEY }}
Tip: Store your n8n base URL and API key as n8n Variables (Settings → Variables). This keeps the workflow portable across environments.

Step 4: Azure OpenAI GPT-4o + Decision Schema

The Azure OpenAI GPT-4o sub-node is the AI brain. Configure it with your Azure endpoint and API key. The Decision Schema (Structured Output Parser) forces the AI to return a predictable structure:

{
  "state": "RETRY" | "FIX",
  "diagnosis": "Human-readable explanation",
  "patch": {
    "parameterName": "broken parameter name",
    "newValue": "corrected value"
  }
}

Step 5: Diagnose Error (AI Agent)

The agent passes this prompt to GPT-4o with full context injected:

You are an n8n Senior Engineer.
Failed Workflow: {{ workflow.name }}
Error: {{ execution.error.message }}
Failed Node: {{ execution.lastNodeExecuted }}
Workflow JSON: {{ full workflow definition }}

Decide: RETRY (transient network error) or FIX (logic/parameter error).
If FIX, identify the broken parameter and provide the corrected value.

Example: if a Google Sheets node fails with “Invalid spreadsheet ID”, GPT-4o reads the workflow JSON, finds the node, and returns a FIX with the corrected documentId.

Step 6: Determine Action (Switch) + Three Paths

Output Condition Path
0: RETRY state === "RETRY" Cool Down (1 min) → Retry Execution
1: FIX state === "FIX" Generate Patch JSON → Update Workflow → Slack success
2: MANUAL Everything else Slack diagnostic alert for human review

For the FIX path, a Code node injects the AI’s corrected value into the workflow JSON, then an HTTP PUT call updates the live workflow via the n8n API. The patched node gets a visible annotation on the canvas so you can see exactly what changed.

Testing Your Workflow

  1. Create a test workflow: Schedule Trigger + HTTP Request to https://httpstat.us/500 (always returns an error).
  2. Set that test workflow’s Error Workflow to this engine.
  3. Execute the test workflow, it will fail immediately.
  4. Check your Slack channel for the diagnosis message within 30 seconds.
Issue Likely Cause Fix
Filter blocks all items Engine is its own Error Workflow Remove self-reference in Settings
401 Unauthorized on API calls API key missing or expired Regenerate key, update N8N_API_KEY variable
AI returns empty patch Error too ambiguous Normal, MANUAL path handles it
No Slack messages Wrong channel ID Right-click Slack channel → Copy Link, use last path segment

Frequently Asked Questions

Does this work on n8n Cloud or only self-hosted?

Both. You just need n8n API access, which is available on all plans. On Cloud, your base URL is something like https://yourname.app.n8n.cloud.

Can I use standard OpenAI instead of Azure OpenAI?

Yes. Swap the Azure OpenAI Chat Model sub-node for a standard OpenAI Chat Model node and connect your OpenAI API key. Everything else stays the same.

What kinds of errors can the AI actually fix automatically?

Common auto-fixable errors: malformed URL parameters, outdated document/spreadsheet IDs, wrong HTTP method, missing required headers, incorrect field names in node parameters. Network timeouts and rate limits go to the RETRY path instead.

Is it safe to let AI update my live workflows automatically?

The engine only patches the single broken parameter in the failed node, and it doesn’t restructure anything. For high-stakes workflows, you can remove the auto-update step and have the AI post the suggested fix to Slack for human approval first.

What happens if the engine itself fails?

The Filter node prevents self-loops. If the engine has its own unhandled error, it stops gracefully without triggering itself. You’ll see the failure in n8n’s execution log like any other workflow.

Can I use Telegram instead of Slack for alerts?

Yes. Replace both Slack nodes with Telegram nodes, set your bot token, and use your Telegram chat ID. The message text is identical, just paste it in.

What’s Next

  • Approval gate: Route FIX suggestions to Slack with approve/reject buttons before auto-applying.
  • Audit log: Add a Google Sheets node at each branch end to log every auto-fix and retry.
  • Frequency escalation: If the same workflow fails more than 3 times in 24 hours, escalate to a high-priority channel or send an email.
  • PagerDuty/OpsGenie integration: For critical production failures that need immediate human response.

Get the AI Self-Healing Engine Template

Stop waking up to broken workflows. The ready-made template includes the complete n8n workflow JSON, a step-by-step Setup Guide PDF, and a Credentials Guide PDF: everything you need to go from zero to running in under 15 minutes.

Buy the template → $14.99

Instant download · Works on n8n Cloud and self-hosted · Lifetime access

How to Build an AI WhatsApp Support Bot with Human Handoff Using n8n, Gemini & Supabase

New to n8n? Start with our step-by-step setup guide, then come back to build this workflow.

Your support team can’t be online 24/7, but your customers expect answers at midnight just as much as noon. The problem with most WhatsApp bots is the binary choice: either the AI handles everything (and frustrates customers when it fails), or a human handles everything (and burns out your team). This n8n workflow solves it differently. The AI answers routine questions instantly, and the moment a human agent jumps in, the bot steps aside. After two hours of silence from the human side, the AI quietly resumes. You get the best of both worlds.

In this guide you’ll build a production-ready WhatsApp support system in n8n using Twilio, Google Gemini, and Supabase vector search. The bot answers questions by searching your own knowledge base documents, can look up customer records in Airtable, maintains per-conversation memory, and handles the AI/human handoff completely automatically.

Prefer to skip the build? Grab the ready-made template → and be live on WhatsApp in under an hour.

What You’ll Build

  1. A Twilio webhook listens for incoming WhatsApp messages from customers.
  2. Before the AI responds, the workflow checks a human-handoff API. If a human agent is active, the bot stays silent.
  3. After 2 hours with no human response, the AI automatically resumes handling the conversation.
  4. The AI agent (powered by Google Gemini) searches your Supabase knowledge base for accurate answers, can look up customer CRM records, and maintains full conversation context via a memory buffer.
  5. Replies go back to the customer via WhatsApp through Twilio.
  6. A separate RAG pipeline keeps the knowledge base fresh: whenever you add or update a document in a Google Drive folder, n8n re-embeds it and syncs to Supabase automatically.

How It Works: The Big Picture

┌──────────────────────────────────────────────────────────────────────────────┐
│  WORKFLOW 1: WhatsApp Chat Handler                                           │
│                                                                              │
│  [Twilio Trigger]                                                            │
│       ↓                                                                      │
│  [Check Human Handoff API]                                                   │
│       ↓                                                                      │
│  [2-Hour Filter] ──(human active + <2h)──→ STOP (human is handling it)      │
│       ↓ (no human, or 2h+ since last response)                              │
│  [Validate Text Input] ──(empty message)──→ STOP                            │
│       ↓                                                                      │
│  [WhatsApp Support Agent (Gemini)]                                           │
│       ├── tool: Knowledgebase RAG (Supabase)                                │
│       ├── tool: CRM Lookup (Airtable)                                       │
│       ├── tool: Think + Calculator                                           │
│       └── memory: Conversation Buffer (per phone number)                    │
│       ↓                                                                      │
│  [Send WhatsApp Reply via email or SMS]                                            │
└──────────────────────────────────────────────────────────────────────────────┘

┌──────────────────────────────────────────────────────────────────────────────┐
│  WORKFLOW 2: Knowledge Base Sync (RAG Pipeline)                              │
│                                                                              │
│  [Google Drive Trigger: file created/updated]                                │
│       ↓                                                                      │
│  [Map File Fields] → [Delete Old Embeddings from Supabase]                  │
│       ↓                                                                      │
│  [Loop Over Files] → [Download from Google Drive]                           │
│       ↓                                                                      │
│  [Load + Chunk Document] → [Embed with OpenAI] → [Store in Supabase]        │
└──────────────────────────────────────────────────────────────────────────────┘

What You’ll Need

  • n8n: cloud or self-hosted (v1.30+)
  • Twilio account: with a WhatsApp-enabled number (~$20/month); Meta business verification required
  • Google Gemini API key: free tier available at aistudio.google.com
  • Supabase account: free tier works; needs the pgvector extension and a documents table
  • OpenAI API key: for generating embeddings (text-embedding-3-small; very cheap)
  • Google Drive folder: where you’ll store your .docx knowledge base files
  • Airtable base: optional, for CRM lookups; remove that tool node if not needed
  • Human handoff dashboard: a simple API that tracks which conversations are currently handled by a human agent (open-source starter available)

Build time from scratch: 3 to 5 hours. With this template: under 60 minutes.


Part 1: The WhatsApp Chat Handler

1 Twilio WhatsApp Trigger: Receive incoming messages

This webhook node fires every time a customer sends a WhatsApp message to your Twilio number. Twilio formats the payload with a data.body field containing the message text and data.from / data.to containing the WhatsApp phone numbers (prefixed with whatsapp:).

To set it up: in Twilio, go to your WhatsApp Sandbox (or verified number) → Messaging → Configure → set the webhook URL to your n8n webhook URL. In n8n, create the credential using your Twilio Account SID and Auth Token.

{
  "data": {
    "body": "Hi, I need help tracking my order #1847",
    "from": "whatsapp:+15559876543",
    "to": "whatsapp:+15551234567"
  }
}
💡

Twilio’s WhatsApp messaging has a 24-hour session window: you can only reply to customers who’ve messaged you first within the last 24 hours. For proactive messages, you’ll need pre-approved Twilio message templates.

2 Check Human Handoff Status: Query the handoff API

This HTTP Request node calls a simple API with the customer’s phone number and gets back a JSON object indicating whether a human agent has taken over, and when they last responded. The API is a lightweight dashboard you deploy separately. A Node.js/Netlify starter is included in the template package.

{
  "humanActive": true,
  "lastHumanResponseTime": "2026-04-10T14:32:00Z"
}

Set the URL parameter to https://YOUR_DASHBOARD_URL/api/check-human?phone={{ $json.data.from.trim() }}.

📌

If you don’t have a handoff dashboard yet, you can stub this out: create a Google Sheet with phone numbers and a “humanActive” column, and replace this node with a Google Sheets lookup. The filter node in Step 3 will then use that value.

3 2-Hour Handoff Filter: Let humans take over

This Filter node uses an OR condition to decide whether the AI should respond: pass the message to the AI if no human is active, OR if the last human response was more than 2 hours ago. If a human agent is actively handling the conversation and responded recently, the filter blocks the item and the AI stays silent.

The two conditions are:

Condition Value Means
humanActive false No human agent is active, AI should respond
lastHumanResponseTime after $now - 2 hours Human hasn’t responded in 2h, AI resumes

4 Validate Text Message: Screen out non-text events

Twilio also fires the webhook for image, audio, and status events. This IF node checks that $('Twilio WhatsApp Trigger').item.json.data.body is not empty, routing only text messages to the AI agent. Non-text events fall through the false branch (which ends here with no action).

5 WhatsApp Support Agent: The AI brain

This is the LangChain Agent node that orchestrates the response. It uses Google Gemini as its language model and has four tools at its disposal: the knowledge base RAG search, a CRM lookup in Airtable, a Think tool for multi-step reasoning, and a Calculator. The Conversation Memory buffer maintains the last 20 messages per phone number, giving the agent full context of the ongoing support conversation.

Customize the system message with your company name, website, support email, and the topics the bot should and shouldn’t discuss. The key constraints to keep:

  • Keep responses under 1,600 characters (WhatsApp best practice)
  • Instruct the agent to say “Let me connect you with a human agent” when it can’t resolve something, your dashboard UI lets agents pick up those flagged conversations
💡

The memory key is set to $json.phoneNumber, which means each phone number gets its own isolated conversation history. If a customer texts from two different numbers, those will be treated as separate conversations.

6 Send WhatsApp Reply: Close the loop

The Twilio node sends the AI’s output back to the customer’s WhatsApp. The from and to fields strip the whatsapp: prefix that Twilio adds to phone numbers, and toWhatsapp: true tells Twilio to route it over WhatsApp instead of SMS.


Part 2: The Knowledge Base RAG Pipeline

The RAG (Retrieval-Augmented Generation) pipeline is what makes the AI actually useful: instead of hallucinating answers, it searches your real company documents. You maintain the knowledge base by uploading .docx files to a Google Drive folder; n8n handles embedding and indexing automatically.

7 Google Drive Triggers: Detect new and updated documents

Two Google Drive Trigger nodes poll a specific folder every minute: one fires on fileCreated, the other on fileUpdated. Both feed into the same processing chain. Set the folder ID by pointing the node to the Drive folder where you’ll store your knowledge base documents (.docx format).

8 Map File Fields + Delete Old Embeddings

The Set node extracts file_id and file_name from the Drive event. Then the Supabase Delete node removes any existing embeddings for that file from the documents table. This is critical for the updated trigger path so you don’t end up with stale duplicate chunks. The delete uses a metadata filter: metadata->>file_id=eq.{{ $json.file_id }}.

9 Loop → Download → Chunk → Embed → Store

The SplitInBatches node processes files one at a time. For each file, n8n downloads the binary from Google Drive, loads it through the Document Loader (configured for .docx files), splits it into chunks using the Recursive Character Text Splitter, generates OpenAI embeddings (1536-dimension, matching the Supabase table setup), and stores the resulting vectors in Supabase.

💡

The Document Loader node embeds the file_id as metadata on each chunk. That’s how the delete step in Step 8 knows which vectors to remove when a file is updated. Don’t remove that metadata configuration.

The Data Structure

Your Supabase documents table needs to be set up with pgvector support. Here’s the required schema:

Column Type Description
id bigserial (primary key) Auto-incrementing row ID
content text The text chunk from your document
metadata jsonb Stores file_id and other chunk metadata
embedding vector(1536) The OpenAI embedding for semantic search

You also need to create a Supabase RPC function called match_documents that performs the vector similarity search. Supabase’s official n8n integration guide provides the exact SQL for this function.

📌

The embedding dimension must match exactly. This workflow uses OpenAI text-embedding-3-small with 1536 dimensions. If you switch to a different embedding model, update both the dimensions parameter in the Embeddings node AND recreate the Supabase column with the matching size.

Full System Flow

Customer sends WhatsApp message
         ↓
  Twilio Webhook (n8n)
         ↓
  Check human handoff API ─────────────── Human dashboard tracks
         ↓                                agent activity per phone
  2-hour filter
         │
         ├─── Human active & recent → SKIP (human handles it)
         │
         └─── No human / expired → continue
                   ↓
          Validate text input
                   ↓
          Gemini Agent
                   ├── Search Supabase ← (vector embeddings from your docs)
                   ├── Lookup Airtable CRM
                   └── Per-phone memory buffer
                   ↓
          Twilio: Send WhatsApp reply
                   ↓
         Customer receives answer

─── Separately (knowledge base sync) ──────────────────────────────
Upload .docx to Google Drive folder
         ↓
  n8n detects new/updated file
         ↓
  Delete old embeddings → Re-embed → Store in Supabase

Testing Your Workflow

Test the chat handler by texting your Twilio WhatsApp sandbox number from your personal phone. Ask a question that’s covered in one of your knowledge base documents and verify the answer is accurate and sourced from your content. Then test the handoff: set humanActive: true in your dashboard for your phone number and send another message, confirm the AI doesn’t respond.

Problem Likely Cause Fix
No reply received Webhook URL not set in Twilio Copy the Twilio Trigger webhook URL into Twilio console → WhatsApp → Configure
AI gives wrong answers Knowledge base not indexed Upload a .docx to the Drive folder and wait for the RAG pipeline to run
Supabase insert fails Dimension mismatch or missing pgvector Enable pgvector in Supabase dashboard; verify column is vector(1536)
Human filter not working Dashboard API returns wrong format Confirm API returns {"humanActive": true/false, "lastHumanResponseTime": "ISO date"}
Memory not persisting Session key wrong The memory node session key must be ={{ $json.phoneNumber }}, check the incoming phone field name

Frequently Asked Questions

Can I use a different AI model instead of Gemini?

Yes. The Google Gemini (AI Brain) node is just the language model sub-node connected to the agent. You can swap it for OpenAI GPT-4o, Anthropic Claude, or any LangChain-compatible model by deleting that node and connecting a different LLM sub-node. The rest of the workflow stays the same.

Do I need the Airtable CRM tool if I don’t use Airtable?

No, it’s optional. If you don’t need CRM lookups, simply delete the CRM Lookup Tool node. The agent will continue working with the remaining tools: Knowledgebase RAG, Think, and Calculator. You could replace it with a Google Sheets lookup, HubSpot, or any other CRM that has an n8n node.

What’s the human handoff dashboard and do I have to build it?

The human handoff dashboard is a small web app (or API endpoint) that lets your support agents see incoming conversations, flag themselves as “active” on a thread, and send manual replies. The original creator of this workflow has an open-source starter on GitHub. Alternatively, if you just want to test the logic first, you can hardcode humanActive: false in the HTTP Request node response and bypass the handoff check entirely.

What document formats does the knowledge base support?

The Document Loader is set to docxLoader by default, which handles .docx files. To support PDFs, switch the loader to pdfLoader. To support plain text or markdown, use textLoader. You can also run multiple RAG pipelines in parallel, each monitoring a different folder and using a different loader.

How does the 2-hour window work exactly?

When a human agent sends a message through the handoff dashboard, the dashboard records the timestamp as lastHumanResponseTime. The n8n Filter node checks if this timestamp is more than 2 hours ago. If yes, the AI is allowed to respond again. You can adjust this window by changing the hours: 2 value in the filter condition. For example, use hours: 4 for a longer human-priority window.

Can this handle images and voice messages?

Not by default. The Validate Text Message node currently passes only non-empty text bodies. To handle images, you’d add an IF branch that checks for data.mediaContentType and routes to an additional OpenAI vision node. Voice messages would require a speech-to-text step (e.g., OpenAI Whisper) before passing to the agent.

🚀 Get the AI WhatsApp Handoff Template

The template includes the complete n8n workflow JSON (clean, importable), a step-by-step Setup Guide PDF, a Credentials Guide PDF walking you through every API key, and the Supabase SQL to set up your vector store.

Buy the template → $14.99

Instant download, works on n8n Cloud and self-hosted

What’s Next

  • Add voice support: Route audio messages through OpenAI Whisper for transcription before passing to the agent.
  • Multilingual detection: Add a language detection step and switch system prompt language to match the customer’s language automatically.
  • Analytics: Log every conversation turn to a Google Sheet or Supabase table to track AI vs. human resolution rates, response times, and common questions.
  • Proactive alerts: Use n8n’s Schedule Trigger to send Twilio template messages (appointment reminders, order updates) proactively to opted-in customers.

How to Automate Zendesk Support with AI Using n8n and RAG

New to n8n? Start with our step-by-step setup guide, then come back to build this workflow.

Your support team is drowning in repetitive tickets while customers wait hours for answers that already exist in your knowledge base. Password resets, shipping questions, “how do I cancel”: the same 20 questions eating up 80% of your agents’ time. What if every new Zendesk ticket got an accurate, knowledge-base-backed AI reply within seconds, and only the genuinely tricky ones reached a human?

That’s exactly what you’ll build in this guide. Using n8n, OpenAI, Supabase, and a RAG (Retrieval-Augmented Generation) pipeline, you’ll create a workflow that reads every incoming Zendesk ticket, searches your knowledge base for relevant answers, generates a professional reply, and posts it directly to the ticket, automatically. When the AI doesn’t have a confident answer, it escalates to your human team with a clear tag so nothing falls through the cracks.

Prefer to skip the setup? Grab the ready-made template and be up and running in under 10 minutes.

What You’ll Build

  1. A new ticket arrives in Zendesk, and the workflow fires instantly via webhook.
  2. The AI agent searches your Supabase-hosted knowledge base using vector similarity (RAG) and drafts a response grounded in your actual documentation.
  3. If the knowledge base has a solid answer, the AI posts the reply directly to the Zendesk ticket and tags it ai_reply.
  4. If the AI can’t find relevant information, it tags the ticket human_requested so your team picks it up, with no guessing, no hallucinations.
  5. Every conversation is stored in Postgres memory, so follow-up tickets from the same customer retain context.

How It Works: The Big Picture

The entire workflow is a single n8n pipeline with a smart routing branch at the end. Here’s the flow from ticket to resolution:

┌──────────────────────────────────────────────────────────────────────────────┐
│  AI-POWERED ZENDESK SUPPORT WITH RAG                                        │
│                                                                              │
│  [Zendesk Webhook] → [Extract Ticket Data] → [RAG AI Agent]                │
│                                                     │                        │
│                                        ┌────────────┴────────────┐          │
│                                         │  Check If Escalation    │         │
│                                        │      Needed             │          │
│                                        └────┬──────────┬─────────┘          │
│                                     YES ↓              ↓ NO                  │
│                               [Tag: human_      [Post AI Reply]             │
│                                requested]              ↓                     │
│                                                  [Tag: ai_reply]            │
│                                                                              │
│  Sub-components of the RAG AI Agent:                                        │
│  ┌──────────────────────────────────────────────┐                            │
│  │ [OpenAI GPT-4o-mini]  [Postgres Memory]      │                           │
│  │ [Knowledge Base Tool → Supabase Vectors]     │                           │
│  │ [OpenAI Embeddings]                         │                           │
│  └──────────────────────────────────────────────┘                           │
└──────────────────────────────────────────────────────────────────────────────┘
  

What You’ll Need

  • n8n: self-hosted or n8n Cloud (any plan)
  • Zendesk: any plan with API access and trigger/webhook support
  • OpenAI API key: for GPT-4o-mini (chat) and text-embedding-3-small (embeddings)
  • Supabase account: free tier works; you’ll need a project with pgvector enabled for the vector store
  • PostgreSQL database: Supabase’s built-in Postgres works, or any external Postgres instance for conversation memory
  • Your knowledge base content: FAQ articles, product docs, troubleshooting guides already written and ready to embed

Estimated build time: 45 to 60 minutes from scratch, or under 10 minutes with the template.

Part 1: Receiving and Parsing Zendesk Tickets

1 Receive New Ticket (Webhook)

This node listens for incoming HTTP POST requests from Zendesk. Every time a new ticket is created, Zendesk’s trigger sends the ticket data to this webhook URL.

  1. Add a Webhook node to your canvas.
  2. Set the HTTP Method to POST.
  3. Set the Path to zendesk-new-ticket (or any slug you prefer).
  4. Copy the generated webhook URL, which you’ll paste this into Zendesk’s trigger configuration.

When a ticket arrives, the webhook receives a JSON payload like this:

{
  "body": {
    "ticket_id": "48291",
    "ticket_status": "new",
    "requester_name": "Sarah Thompson",
    "requester_email": "sarah.thompson@gmail.com",
    "subject": "Can't reset my password",
    "description": "Hi, I've been trying to reset my password for the last hour but the reset email never arrives. I've checked spam. Can you help?"
  }
}
💡

Tip: In Zendesk, go to Admin Center → Objects and rules → Triggers. Create a trigger that fires when “Ticket is Created” and set the action to “Notify active webhook” with your n8n webhook URL. Include ticket_id, subject, description, requester_name, requester_email, and ticket_status as JSON fields in the webhook body.

2 Extract Ticket Data (Set Node)

The raw webhook payload is nested inside body. This Set node extracts the fields you need into clean, top-level variables that the rest of the workflow can reference easily.

  1. Add a Set node after the Webhook.
  2. Create assignments for: ticket_id, ticket_status, requester_name, requester_email, subject, description, and timestamp.
  3. For description, use the expression {{ ($json.body.description || '').split('\n\n').slice(-1)[0].trim() }}, which strips quoted reply chains and keeps only the customer’s latest message.
  4. For timestamp, use {{ $now.format('yyyy-MM-dd HH:mm') }} so you have a record of when the workflow processed the ticket.

After this node, the data flowing forward looks like:

{
  "ticket_id": "48291",
  "ticket_status": "new",
  "requester_name": "Sarah Thompson",
  "requester_email": "sarah.thompson@gmail.com",
  "subject": "Can't reset my password",
  "description": "I've been trying to reset my password for the last hour but the reset email never arrives. I've checked spam. Can you help?",
  "timestamp": "2026-04-10 14:23"
}

Part 2: The RAG AI Agent

This is the brain of the workflow. The AI Agent node connects to three sub-components: a language model (GPT-4o-mini), a conversation memory (Postgres), and a knowledge base retrieval tool (Supabase vector store). Together, they form a RAG pipeline that grounds every response in your actual documentation.

3 Generate AI Response (AI Agent)

The Agent node receives the customer’s ticket and orchestrates the entire reasoning process. It decides whether to search the knowledge base, reads the results, and composes a professional reply.

  1. Add an AI Agent node.
  2. Set the Prompt Type to Define.
  3. Set the input text to:
    Customer: {{ $json.requester_name }}
    Subject: {{ $json.subject }}
    Message: {{ $json.description }}
  4. In the System Message, paste the following instructions that tell the agent how to behave:
You are a professional, empathetic customer support agent. Your job is to help
customers by answering their questions accurately using ONLY the information
from the retrieved knowledge base documents.

Rules:
1. Always be polite, professional, and concise.
2. If the knowledge base contains a clear answer, provide it with step-by-step
   instructions when appropriate.
3. If the knowledge base does NOT contain relevant information, respond with
   EXACTLY: "I will escalate this to our support team who will get back to
   you shortly."
4. Never make up information. Never guess. Only use verified KB content.
5. Sign off with: "Best regards, Support Team"
📌

The exact escalation phrase, “will escalate this” / “get back to you shortly”, is critical. The routing node downstream checks for these phrases to decide whether to post the reply or tag for human review. Don’t change this wording unless you also update the IF condition.

4 OpenAI Chat Model (Sub-node)

This is the language model that powers the agent’s reasoning. It connects to the Agent node’s ai_languageModel input.

  1. Add an OpenAI Chat Model node below the Agent.
  2. Select gpt-4o-mini as the model: it’s fast, cheap, and accurate enough for support responses.
  3. Set temperature to 0.3: low enough to keep answers factual, high enough to sound natural.
  4. Set max tokens to 1024, more than enough for a support reply.
  5. Connect your OpenAI API credential.
💡

Tip: If you need higher-quality reasoning for complex product questions, swap to gpt-4o. The cost goes up roughly 10x per token, but accuracy improves noticeably for technical troubleshooting.

5 Ticket Conversation Memory (Postgres)

This memory node stores the conversation history for each ticket ID in a Postgres table called zendesk_ticket_histories. If a customer sends a follow-up message on the same ticket, the AI remembers what was discussed before.

  1. Add a Postgres Chat Memory node.
  2. Set the table name to zendesk_ticket_histories.
  3. Set the Session Key to {{ $('Extract Ticket Data').item.json.ticket_id }}: this groups messages by ticket.
  4. Connect your Postgres credential (Supabase’s built-in Postgres works perfectly here).

The table is created automatically on first run. It stores each message exchange so the agent has full context for multi-message tickets.

6 Knowledge Base Retrieval Tool (Vector Store)

This is the RAG component. The tool searches your Supabase vector store for the most relevant knowledge base articles and feeds them to the AI agent as context.

  1. Add a Vector Store Tool node and name it “Retrieve Knowledge Base”.
  2. Set the tool name to knowledge_base.
  3. Set Top K to 5: the agent will receive the 5 most relevant document chunks.
  4. Write a clear description: “Contains all company knowledge base articles, FAQs, product documentation, and troubleshooting guides.”

7 Supabase Vector Store + OpenAI Embeddings

The Vector Store Tool needs two sub-components: a vector store (where your documents live) and an embedding model (to convert the search query into a vector).

  1. Add a Supabase Vector Store node. Set the table to documents and the query function to match_documents.
  2. Add an OpenAI Embeddings node. Set the model to text-embedding-3-small with 1536 dimensions.
  3. Wire the Embeddings node into the Vector Store’s ai_embedding input.
  4. Wire the Vector Store into the Retrieve Knowledge Base tool’s ai_vectorStore input.
💡

Tip: To populate your Supabase vector store, create a separate n8n workflow that reads your KB articles (from Google Docs, Notion, or markdown files), splits them into chunks of ~500 tokens, generates embeddings with the same model (text-embedding-3-small), and inserts them into the documents table. This only needs to run once (or whenever you update your docs).

Part 3: Smart Routing and Zendesk Actions

After the AI generates a response, the workflow needs to decide: was the response a confident answer, or did the AI punt because it couldn’t find relevant information?

8 Check If Escalation Needed (IF Node)

This IF node inspects the AI’s output text. If it contains the escalation phrases (“will escalate this” or “get back to you shortly”), the ticket goes to the human escalation path. Otherwise, it proceeds to auto-reply.

  1. Add an IF node after the AI Agent.
  2. Set the condition combinator to OR.
  3. Condition 1: {{ $json.output }} contains will escalate this
  4. Condition 2: {{ $json.output }} contains get back to you shortly
  5. Set case sensitivity to false.

The True branch (escalation needed) goes to the human tagging node. The False branch (AI answered) goes to the reply-posting node.

9 Tag as Human Escalation (True Branch)

When the AI can’t find an answer, this HTTP Request node calls the Zendesk API to tag the ticket with human_requested and ai_escalated. Your support team can create a Zendesk view filtered by these tags to see exactly which tickets need human attention.

  1. Add an HTTP Request node on the True output.
  2. Set Method to PUT.
  3. Set URL to: https://YOUR_ZENDESK_DOMAIN.zendesk.com/api/v2/tickets/{{ $('Extract Ticket Data').first().json.ticket_id }}/tags.json
  4. Set the JSON body to: { "tags": ["human_requested", "ai_escalated"] }
  5. Set authentication to Predefined Credential Type → Zendesk API.

10 Post AI Reply to Ticket (False Branch)

When the AI has a confident answer, this node posts it as a public comment on the Zendesk ticket and sets the ticket status to “pending” (awaiting customer confirmation).

  1. Add an HTTP Request node on the False output.
  2. Set Method to PUT.
  3. Set URL to: https://YOUR_ZENDESK_DOMAIN.zendesk.com/api/v2/tickets/{{ $('Extract Ticket Data').first().json.ticket_id }}.json
  4. Set the JSON body to:
{
  "ticket": {
    "comment": {
      "body": "{{ AI agent's output text }}",
      "public": true
    },
    "status": "pending"
  }
}

The "public": true flag means the customer sees this reply in their email and in the Zendesk portal. Setting status to "pending" tells Zendesk to wait for the customer’s next response.

11 Tag as AI Reply

After posting the reply, this final node tags the ticket with ai_reply and auto_resolved. This lets you track how many tickets the AI handles versus humans, and gives you data for measuring automation ROI.

  1. Add one more HTTP Request node after the reply node.
  2. Same pattern: PUT to the /tags.json endpoint.
  3. Body: { "tags": ["ai_reply", "auto_resolved"] }

The Data Structure

The workflow relies on two persistent data stores: the Supabase vector store for knowledge base content, and the Postgres table for conversation memory.

Supabase documents Table

Column Type Example Description
id bigint 1 Auto-incrementing primary key
content text To reset your password, go to Settings → Security → Change Password… The raw text chunk from your KB article
metadata jsonb {“source”: “password-reset-guide”, “section”: “steps”} Source tracking: which article and section this chunk came from
embedding vector(1536) [0.0023, -0.0119, …] Vector embedding generated by text-embedding-3-small

Postgres zendesk_ticket_histories Table

Column Type Example Description
session_id text 48291 The Zendesk ticket ID, which groups all messages for one ticket
message text {“type”:”human”,”content”:”I can’t reset my password…”} Individual message in the conversation
created_at timestamp 2026-04-10 14:23:00 When the message was stored
📌

The zendesk_ticket_histories table is created automatically by n8n’s Postgres Chat Memory node on first execution. You don’t need to create it manually. The documents table and its match_documents function must be set up in Supabase before the workflow will work. See the Credentials Guide for full setup steps.

Full System Flow

┌─────────────────────────────────────────────────────────────────────────────┐
│  END-TO-END: TICKET ARRIVES → RESOLUTION                                   │
│                                                                             │
│  Customer creates ticket in Zendesk                                        │
│       ↓                                                                     │
│  Zendesk Trigger fires webhook POST                                        │
│       ↓                                                                     │
│  [Receive New Ticket] — n8n webhook catches the request                    │
│       ↓                                                                     │
│  [Extract Ticket Data] — pull ticket_id, subject, description, etc.        │
│       ↓                                                                     │
│  [Generate AI Response] ← GPT-4o-mini + Postgres Memory                   │
│       │                  ← Knowledge Base Tool                              │
│       │                     ↑                                               │
│       │              [Supabase Vectors] ← [OpenAI Embeddings]              │
│       ↓                                                                     │
│  [Check If Escalation Needed]                                              │
│       │                                                                     │
│   YES ├──→ [Tag: human_requested] → Human agent picks up ticket            │
│       │                                                                     │
│    NO └──→ [Post AI Reply to Ticket] → Customer gets instant answer        │
│                    ↓                                                        │
│            [Tag: ai_reply] → Track AI resolution rate                      │
└─────────────────────────────────────────────────────────────────────────────┘
  

Testing Your Workflow

  1. Activate the workflow in n8n (toggle the Active switch).
  2. Create a test ticket in Zendesk with a question your knowledge base can answer, for example, “How do I reset my password?”
  3. Check the n8n execution log: you should see the webhook trigger, data extraction, AI agent processing, and the reply being posted.
  4. Open the Zendesk ticket: verify the AI’s reply appears as a public comment and the ticket has the ai_reply tag.
  5. Create a second test ticket with a question your KB does NOT cover, like “Can I get a refund for my order #12345?”
  6. Verify escalation: the ticket should have the human_requested tag and no AI reply posted.
Problem Likely Cause Fix
Webhook never fires Zendesk trigger not configured or wrong URL Double-check the webhook URL in Zendesk Admin → Triggers. Make sure the trigger condition is “Ticket is Created.”
AI returns generic/wrong answers Knowledge base not populated or embeddings mismatch Verify your documents table has content. Ensure you used text-embedding-3-small with 1536 dimensions when inserting docs.
AI always escalates Vector search returns no results Check that the match_documents Postgres function exists in Supabase and the table name matches exactly.
Reply not appearing on ticket Zendesk API auth error or wrong domain Verify your Zendesk API credential has write access and the domain in the URL matches your subdomain (e.g., mycompany.zendesk.com).
“401 Unauthorized” on tag update Zendesk credential lacks admin scope The API token needs to be created by an admin user. Go to Admin → Channels → API and generate a new token.

Frequently Asked Questions

How much does it cost to run this per ticket?

With GPT-4o-mini and text-embedding-3-small, the average cost is about $0.002 to $0.005 per ticket (input + output tokens combined). If you process 1,000 tickets per month, that’s roughly $2 to $5/month in OpenAI costs. Supabase’s free tier handles up to 500MB of vector data, which is plenty for most knowledge bases.

Can I use this with Zendesk’s free plan?

No, you need API access and the ability to create triggers/webhooks, which requires Zendesk Suite Team or higher. The trigger feature that sends webhook notifications on ticket creation is not available on the free/lite plans.

What happens if the AI gives a wrong answer?

Since the agent is configured with strict RAG-only instructions and a low temperature (0.3), hallucinations are rare. But they can happen. We recommend reviewing AI-tagged tickets weekly during the first month and adjusting your KB content where gaps appear. You can also lower the temperature to 0.1 for even more conservative responses.

Can I add more languages to the knowledge base?

Yes. OpenAI’s embedding model supports 100+ languages natively. If your KB articles are in Spanish or French, the vector search will still work, since the embedding model handles cross-lingual similarity. Just make sure your system prompt tells the agent to reply in the customer’s language.

How do I update the knowledge base when we add new articles?

Create a second n8n workflow that watches your documentation source (Google Drive, Notion, or a webhook from your CMS). When a document changes, the workflow re-chunks it, generates new embeddings, and upserts them into the Supabase documents table. This keeps your AI current without manual intervention.

Does this work with Freshdesk, Intercom, or other helpdesks?

The core RAG pipeline (AI Agent + Supabase + Embeddings) works with any helpdesk that has a webhook or API. You’d swap the Zendesk-specific webhook trigger and HTTP Request nodes for the equivalent in your helpdesk. The logic is identical, only the API endpoints change.

Get the AI Zendesk Support Template

Skip the 60-minute build. Get the complete workflow JSON, Supabase setup instructions, and a step-by-step credentials guide. Paste your API keys and go live in under 10 minutes.

Get the Template

Instant download · Works on n8n Cloud and self-hosted

What’s Next?

  • Add a satisfaction survey: after the AI replies, send a follow-up asking the customer to rate the response. Use the rating to fine-tune your KB.
  • Build a KB ingestion pipeline: automate the process of embedding new documentation into Supabase whenever you publish a new help article.
  • Add Slack notifications for escalations: when a ticket is tagged human_requested, send a Slack message to your support channel so agents can pick it up immediately.
  • Track AI resolution rate: build a simple dashboard (Google Sheets or Metabase) that counts ai_reply vs human_requested tags over time to measure your automation ROI.
n8n
Zendesk
OpenAI
Supabase
RAG
Customer Support
automation

How to Build an AI Chatbot That Queries Your Baserow Database with n8n

New to n8n? Start with our step-by-step setup guide, then come back to build this workflow.

Your team keeps pinging you with the same questions: “What’s the status on the Carter account?” or “How many orders came in from Texas last week?” The answers already live in your database. The problem is that nobody wants to learn how to query it. What if they could just ask, in plain English, and get the answer back in seconds? That’s exactly what you’ll build in this guide: an AI chatbot powered by n8n, OpenAI GPT-4o Mini, and Baserow that lets anyone on your team talk to your data without writing a single query.

Prefer to skip the setup? Grab the ready-made template → and be up and running in under 10 minutes.

What You’ll Build

  1. A user opens the n8n chat widget and types a question like “Show me all pending orders from California.”
  2. An AI agent interprets the question, queries your Baserow database for matching records, and formats the results.
  3. The chatbot replies with a clear, readable answer: no SQL, no filters, no training needed.
  4. Follow-up questions work naturally because the chatbot remembers the conversation context.

How It Works: The Big Picture

The whole system is a single n8n workflow with four connected components. The Chat Trigger receives the user’s message, passes it to an AI Agent that decides what to look up, queries Baserow through a built-in tool, and streams the answer back, all while keeping a memory buffer so the conversation flows naturally.

┌──────────────────────────────────────────────────────────────────────┐
│  AI CHATBOT — QUERY BASEROW DATABASE                                │
│                                                                      │
│  [Chat Trigger] ──→ [Database Query Agent] ──→ Chat Response         │
│                           │       │                                  │
│                    ┌──────┘       └──────┐                           │
│                    ↓                     ↓                           │
│           [OpenAI GPT-4o Mini]   [Conversation Memory]               │
│                                         │                            │
│                                  [Query Baserow]                     │
│                                    (AI Tool)                         │
└──────────────────────────────────────────────────────────────────────┘
  

What You’ll Need

  • A self-hosted or cloud n8n instance (version 1.0 or later)
  • An OpenAI account with an API key. GPT-4o Mini costs roughly $0.15 per million input tokens, so this is very affordable
  • A Baserow account (free tier works) with at least one database table containing the data you want to query
  • About 15 minutes to set everything up from scratch

Estimated build time: 15 to 20 minutes from scratch, or under 5 minutes with the template.

Building the Chatbot: Step by Step

1 Chat Trigger (Chat Trigger Node)

This is the entry point. The Chat Trigger node creates a built-in chat widget inside n8n where users can type their questions. When someone sends a message, the node captures the text and passes it downstream.

  1. In your n8n canvas, click Add node and search for Chat Trigger.
  2. Drop it on the canvas. The default settings work, no configuration needed.
  3. This node will automatically generate a chat URL you can share, or you can embed the widget on any page.

After this node fires, the data looks like this:

{
  "chatInput": "Show me all pending orders from California",
  "sessionId": "a7f3e2b1-9c4d-4e8a-b5f6-1234567890ab"
}
💡

Tip: Each conversation gets a unique sessionId. The memory node uses this to keep separate conversation threads, so multiple people can chat at the same time without mixing up context.

2 Database Query Agent (AI Agent Node)

The AI Agent is the brain of this workflow. It receives the user’s question, decides whether it needs to query the database, calls the Baserow tool if needed, and composes a human-readable response. Think of it as a smart middleman between your user and your data.

  1. Add an AI Agent node and connect it to the Chat Trigger’s output.
  2. Open the node settings and find the System Message field under Options.
  3. Paste this system prompt (customize it to describe your specific data):
You are a helpful data assistant. Your job is to answer user questions by querying the connected Baserow database.

Rules:
1. Always use the Baserow tool to look up real data before answering.
2. If the user asks a question you cannot answer from the database, say so clearly.
3. Format numbers, dates, and lists in a readable way.
4. Keep answers concise: summarize large result sets instead of dumping raw rows.
5. If the query returns no results, suggest the user rephrase or check their filters.
💡

Tip: The more specific your system prompt is about your data schema, the better the agent performs. If your table has columns like order_status, customer_state, and total_amount, mention them in the prompt so the agent knows exactly what fields to filter on.

3 OpenAI GPT-4o Mini (Chat Model Node)

This node provides the language model that powers the agent’s reasoning. GPT-4o Mini is the sweet spot here: it’s fast, cheap (fractions of a cent per query), and accurate enough for database lookups and conversational responses.

  1. Add an OpenAI Chat Model node (@n8n/n8n-nodes-langchain.lmChatOpenAi).
  2. Connect it to the AI Language Model input on the Agent node (the bottom-left connector).
  3. Set the Model to gpt-4o-mini.
  4. Under Options, set Temperature to 0.3, you want factual, consistent answers, not creative ones.
  5. Set Max Tokens to 2048, enough for detailed responses without runaway costs.
  6. Select your OpenAI credential (or create a new one by pasting your API key).
📌

You can swap in gpt-4o for more complex reasoning, but for most database Q&A tasks, GPT-4o Mini handles the job well and costs about 10x less.

4 Conversation Memory (Buffer Window Memory Node)

Without memory, every message would be a brand-new conversation. The Buffer Window Memory node stores the last 12 exchanges so the agent understands context. When a user asks “What about New York?” right after asking about California orders, the agent knows they mean orders from New York.

  1. Add a Window Buffer Memory node.
  2. Connect it to the AI Memory input on the Agent node (the bottom-center connector).
  3. Set Session ID Type to From Input, this uses the Chat Trigger’s session ID automatically.
  4. Set Context Window Length to 12. This means the agent remembers the last 12 messages (6 pairs of user + assistant).
💡

Tip: If your users tend to ask long, multi-part questions, increase the window to 20. If you want to save on token costs, drop it to 6. The trade-off is context awareness vs. cost per conversation.

5 Query Baserow (Baserow Tool Node)

This is where the magic happens. The Baserow Tool node gives the AI Agent the ability to search, filter, and read rows from your Baserow table. The agent decides when to use it and what to search for. You just need to point it at the right table.

  1. Add a Baserow node (specifically the Baserow Tool variant for AI agents).
  2. Connect it to the AI Tool input on the Agent node (the bottom-right connector).
  3. Select your Baserow credential (API token, you’ll find this in your Baserow account settings).
  4. Set the Database ID: you can find this in your Baserow URL: https://baserow.io/database/YOUR_ID.
  5. Set the Table ID: click into any table and check the URL for the table number.

When the agent calls this tool, it gets back rows like this:

[
  {
    "id": 142,
    "order_id": "ORD-2026-0891",
    "customer_name": "James Carter",
    "customer_email": "james.carter@gmail.com",
    "customer_state": "CA",
    "order_status": "Pending",
    "total_amount": 249.99,
    "created_at": "2026-04-07"
  },
  {
    "id": 143,
    "order_id": "ORD-2026-0892",
    "customer_name": "Emily Rodriguez",
    "customer_email": "emily.rodriguez@outlook.com",
    "customer_state": "CA",
    "order_status": "Pending",
    "total_amount": 89.50,
    "created_at": "2026-04-08"
  }
]

The agent then reads this data, formats it, and responds to the user with something like: “There are 2 pending orders from California: one for James Carter ($249.99) and one for Emily Rodriguez ($89.50), totaling $339.49.”

The Data Structure

Your Baserow table is the foundation of this whole system. The chatbot can only answer questions about data that exists in your table, so the schema matters. Here’s an example for an order tracking table:

Column Type Example Description
order_id Text ORD-2026-0891 Unique order identifier
customer_name Text James Carter Full name of the customer
customer_email Email james.carter@gmail.com Customer contact email
customer_state Text CA Two-letter US state code
order_status Single Select Pending Current status: Pending, Shipped, Delivered, Cancelled
total_amount Number 249.99 Order total in USD
created_at Date 2026-04-07 Date the order was placed
📌

Column names should be descriptive and snake_case. The AI agent uses column names to understand what each field contains, so customer_state works much better than col_7. If your existing table has cryptic column names, consider renaming them. It makes a real difference in answer quality.

Here’s what the data lifecycle looks like with a few sample rows:

order_id customer_name customer_state order_status total_amount
ORD-2026-0891 James Carter CA Pending $249.99
ORD-2026-0887 Sarah Thompson TX Shipped $175.00
ORD-2026-0879 Michael Chen NY Delivered $312.50

Full System Flow

┌─────────────────────────────────────────────────────────────────────────┐
│                                                                         │
│  USER types question          n8n CHAT WIDGET                           │
│  "Show pending CA orders"  →  [Chat Trigger]                            │
│                                     │                                   │
│                                     ▼                                   │
│                            [Database Query Agent]                       │
│                             GPT-4o Mini brain                           │
│                                │         │                              │
│                      ┌─────────┘         └──────────┐                   │
│                      ▼                              ▼                   │
│             [Conversation Memory]          [Query Baserow]              │
│              12-message window              Reads table rows            │
│                                                    │                    │
│                                                    ▼                    │
│                                          ┌─────────────────┐           │
│                                          │  BASEROW TABLE   │           │
│                                          │  Orders, Leads,  │           │
│                                          │  Inventory, etc. │           │
│                                          └─────────────────┘           │
│                                                    │                    │
│                      ▼                             │                    │
│           Agent formats answer  ◄──────────────────┘                    │
│                      │                                                  │
│                      ▼                                                  │
│  USER receives      "There are 2 pending orders                         │
│  formatted answer    from California totaling $339.49"                  │
│                                                                         │
└─────────────────────────────────────────────────────────────────────────┘
  

Testing Your Workflow

  1. Save your workflow and make sure all four nodes are connected (Chat Trigger → Agent, with the model, memory, and tool feeding into the Agent’s sub-connectors).
  2. Click Chat in the bottom-right of the n8n canvas to open the built-in chat panel.
  3. Type a simple question: How many rows are in the table? This tests the basic connection.
  4. Ask a filtered question: Show me all orders from California This tests the agent’s ability to apply filters.
  5. Ask a follow-up: Which of those are still pending? This tests conversation memory.
  6. Ask something the database can’t answer: What's the weather in Chicago? The agent should politely decline.
Problem Likely Cause Fix
Agent says “I don’t have access to any tools” Baserow Tool node not connected to the Agent’s AI Tool input Check the connection, it should link to the wrench/tool connector on the Agent node, not the main input
Agent returns empty results for valid queries Wrong Database ID or Table ID in the Baserow node Double-check both IDs against your Baserow URL, they’re numeric IDs, not names
“Authentication failed” error Invalid or expired Baserow API token Generate a new token in Baserow → Settings → API tokens, and update the credential in n8n
Follow-up questions don’t work Memory node not connected or Session ID not set Ensure the Buffer Window Memory connects to the AI Memory port, and Session ID Type is set to “From Input”
Responses are slow (10+ seconds) Large table with thousands of rows Add a view filter in Baserow to limit the rows the tool can access, or switch to a more targeted query setup

Frequently Asked Questions

Can I use this with a free Baserow account?

Yes. Baserow’s free tier includes API access, which is all this workflow needs. The free plan supports up to 3,000 rows per table. If your dataset is larger, you’ll need a paid Baserow plan or a self-hosted instance.

How much does it cost to run per month?

Very little. GPT-4o Mini charges roughly $0.15 per million input tokens and $0.60 per million output tokens. A typical database query conversation uses about 2,000 to 4,000 tokens total. If your team runs 100 queries per day, you’re looking at maybe $2 to $5 per month in OpenAI costs. The n8n and Baserow free tiers cover everything else.

Can I connect multiple tables to the same chatbot?

Yes, add additional Baserow Tool nodes for each table and connect them all to the Agent’s AI Tool input. The agent will decide which table to query based on the user’s question. Just make sure your system prompt describes what each table contains so the agent picks the right one.

Can I embed the chat widget on my website?

n8n’s Chat Trigger generates a URL that you can embed as an iframe or integrate with n8n’s chat widget library. For production use, you might want to swap the Chat Trigger for a Webhook node and build a custom frontend, but for internal team use, the built-in widget works great.

What if I want to use Google Sheets instead of Baserow?

Swap the Baserow Tool node for a Google Sheets Tool node (or use an HTTP Request tool with the Sheets API). The rest of the workflow stays the same. Baserow has an edge for structured queries because it supports filters natively, but Google Sheets works fine for smaller datasets.

Is my data sent to OpenAI?

Yes, the rows retrieved from Baserow are sent to OpenAI as part of the prompt so the model can formulate an answer. If you’re working with sensitive data, review OpenAI’s data usage policy or consider using a self-hosted LLM (like Ollama) instead of GPT-4o Mini.

Get the Baserow AI Chatbot Template

Skip the setup and get the pre-built workflow JSON, a step-by-step setup guide, and a credentials walkthrough so you’re live in under 5 minutes.

Get the Template →

Instant download · Works on n8n Cloud and self-hosted

What’s Next?

  • Add a Slack or Telegram interface: replace the Chat Trigger with a Slack or Telegram trigger so your team can query the database directly from their messaging app.
  • Connect multiple data sources: add Airtable, Google Sheets, or a Postgres database alongside Baserow to build a unified data assistant.
  • Add write capabilities: extend the agent with a Baserow “create row” tool so users can add or update records through the chat (e.g., “Mark order ORD-2026-0891 as shipped”).
  • Schedule automated reports: add a Schedule Trigger that runs a predefined query every morning and sends the results to your team channel.
n8n
Baserow
OpenAI
GPT-4o Mini
AI Agent
chatbot
database automation
no-code

How to Build an AI Chatbot with Long-Term Memory Using n8n and Google Docs

New to n8n? Start with our step-by-step setup guide, then come back to build this workflow.

Ever built a chatbot that forgets everything the moment the conversation ends? You ask your AI assistant to remember your coffee order preference, and five minutes later it has no idea you’re a oat-milk double-shot latte person. It’s frustrating, and it makes the experience feel less intelligent than it should be.

Here’s the good news: you can fix this with n8n. This workflow gives your AI chatbot true persistent memory using Google Docs as a beautifully simple, completely free knowledge store. No database setup. No complex infrastructure. Just your chatbot learning about users, remembering details, and getting smarter with every conversation.

Ready to build this? You can grab the complete ready-to-import workflow with all the setup instructions at EasyWorkflows. Import in seconds and start building immediately.

What You’ll Build

This workflow creates an intelligent chatbot experience where:

  1. Users send messages via chat trigger (or Telegram)
  2. The workflow instantly retrieves all previous memories and notes about that user from Google Docs
  3. An AI agent (GPT-4o-mini) reads the incoming message alongside historical context
  4. The AI thinks about what to remember, what to save, and how to respond
  5. Important facts get saved to the “Long-Term Memories” doc for persistence
  6. Temporary notes get saved to the “Notes” doc for session context
  7. The response goes back to the user via Telegram, chat interface, or both

How It Works: The Big Picture

Let me show you the architecture before we dive into the build:

┌─────────────────────────────────────────────────────────────────┐
│                         USER MESSAGE                             │
│                  (Chat Trigger / Telegram)                       │
└────────────────────────────┬────────────────────────────────────┘
                             │
                ┌────────────┴────────────┐
                │                         │
      ┌─────────▼──────────┐   ┌─────────▼──────────┐
      │   Load Memories    │   │    Load Notes      │
      │  from Google Docs  │   │  from Google Docs  │
      │   (Memory Doc)     │   │   (Notes Doc)      │
      └─────────┬──────────┘   └─────────┬──────────┘
                │                         │
                └────────────┬────────────┘
                             │
                      ┌──────▼──────┐
                      │    Merge    │
                      │ Memories &  │
                      │    Notes    │
                      └──────┬──────┘
                             │
                      ┌──────▼──────┐
                      │  Combine    │
                      │  Context    │
                      └──────┬──────┘
                             │
        ┌────────────────────┼────────────────────┐
        │                    │                    │
   ┌────▼────┐      ┌────────▼────────┐     ┌────▼────┐
   │ Session │      │  AI Memory      │     │  GPT-   │
   │ Memory  │      │  Agent (with    │     │ 4o Mini │
   │ Buffer  │      │  System Prompt) │     │         │
   └────┬────┘      └────────┬────────┘     └────┬────┘
        │                    │                    │
        └────────────────────┼────────────────────┘
                             │
                ┌────────────┴────────────┐
                │                         │
      ┌─────────▼────────┐    ┌──────────▼──────────┐
      │  Save Memory to  │    │  Save Note to      │
      │   Google Docs    │    │  Google Docs       │
      │  (Triggered by   │    │  (Triggered by AI) │
      │   AI decision)   │    │                    │
      └─────────┬────────┘    └──────────┬──────────┘
                │                        │
      ┌─────────▼──────────────────────────▼────────┐
      │              Response Output                │
      │      (Format Chat + Send Telegram)          │
      └──────────────────────────────────────────────┘

What You’ll Need

Before you start, gather these prerequisites:

  • n8n account (cloud.n8n.io or self-hosted), free tier works fine
  • OpenAI API key with GPT-4o-mini access (~$0.15 per conversation)
  • Google account with Google Docs access (free)
  • Telegram account (optional, but included in this workflow)
  • Telegram Bot Token from BotFather (optional, only if using Telegram output)
  • Basic n8n knowledge: familiarity with nodes, connections, and expressions is helpful but not required

Time estimate: 25 to 35 minutes for setup and first conversation.

Setting Up Your Google Docs

Google Docs is the memory backbone of this workflow. Think of it like a simple, searchable database that the AI can read and write to. Here’s why it works so well:

  • Free: You don’t pay per request or storage
  • Human-readable: You can open it anytime and read what the AI has learned
  • Searchable: Built-in Find function means you can track memory growth
  • OAuth2-compatible: n8n integrates seamlessly
  • Shareable: If you want to audit or share user data with a team member, it’s just a Google Doc link

Create Two Google Docs

Doc 1: “Long-Term Memories”

This stores facts that persist across conversations. Examples:

[04/08/2026] - Name: Sarah
[04/08/2026] - Preference: Oat milk lattes, no sugar
[04/08/2026] - Job: Product Manager at TechCorp
[04/08/2026] - Timezone: America/Chicago
[04/08/2026] - Goal: Learn n8n automation

Doc 2: “Notes”

This stores temporary reminders, action items, and session notes:

[04/08/2026 14:32:15] - User asked about workflow pricing
[04/08/2026 14:33:42] - Follow up: send template examples
[04/08/2026 14:35:08] - User mentioned bandwidth limits in n8n Cloud

You’ll get the document IDs after you create them. In Google Docs, the URL looks like:

https://docs.google.com/document/d/YOUR_GOOGLE_DOC_ID/edit

Copy that ID. You’ll paste it into the workflow nodes.

Building the Workflow: Step by Step

Now let’s build this. I’ll walk through each node with configurations and tips.

1 Chat Trigger

What it does: Listens for incoming messages from the n8n chat interface or external webhooks. This is your entry point for user input.

How to configure:

  • In n8n, add a “Chat Trigger” node (n8n-nodes-base.chatTrigger)
  • Set chatTriggerType to "webhook"
  • Save and deploy the workflow
  • The node will generate a webhook URL automatically

Data that flows out:

{
  "chatId": "user-session-123",
  "message": "Hey, can you remember I prefer oat milk lattes?",
  "sessionId": "session-456"
}

Tip: The Chat Trigger can receive messages from n8n’s web chat UI, Telegram, Slack, or any HTTP POST request. In this workflow, it fans out to two parallel Google Docs fetch operations.

2 Load Memories from Google Docs

What it does: Retrieves the Long-Term Memories document. This gives the AI context about the user’s past.

How to configure:

  • Add a “Google Docs” node
  • Authenticate with your Google account (OAuth2)
  • Set resource to "document"
  • Set documentId to YOUR_GOOGLE_DOC_ID_MEMORIES
  • Set option to "getText"

Data that flows out:

{
  "data": "[04/08/2026] - Name: Sarah\n[04/08/2026] - Preference: Oat milk lattes, no sugar\n[04/08/2026] - Job: Product Manager at TechCorp"
}

Tip: This node runs in parallel with the Notes fetch, so both operations happen simultaneously. The latency is usually under 500ms per fetch.

3 Load Notes from Google Docs

What it does: Retrieves the Notes document. This provides immediate session context and recent reminders.

How to configure:

  • Add another “Google Docs” node (separate from the Memories node)
  • Authenticate with the same Google account
  • Set resource to "document"
  • Set documentId to YOUR_GOOGLE_DOC_ID_NOTES
  • Set option to "getText"

Data that flows out:

{
  "data": "[04/08/2026 14:32:15] - Asked about workflow pricing\n[04/08/2026 14:33:42] - Follow up: send template examples"
}

Tip: If the Notes doc doesn’t exist yet or is empty, the node will return an empty string. That’s fine. The workflow handles it gracefully.

4 Merge Memories & Notes

What it does: Combines the two separate outputs into a single data structure. This merge prepares the data for aggregation.

How to configure:

  • Add a “Merge” node (@n8n-nodes-base.merge)
  • Set mode to "combine"
  • Set combineBy to "id"
  • Connect Memories output to input 0
  • Connect Notes output to input 1

Data that flows out:

[
  { "json": { "data": "[memories...]", "type": "memories" } },
  { "json": { "data": "[notes...]", "type": "notes" } }
]

Tip: The Merge node in “combine” mode takes multiple inputs and creates an array. This makes it easy for the next node to iterate over both data sources.

5 Combine Context

What it does: Aggregates the memories and notes into a single context object that the AI agent will receive.

How to configure:

  • Add an “Aggregate” node (@n8n-nodes-base.aggregate)
  • Set mode to "combine"
  • Leave other options as default

Data that flows out:

{
  "memory_context": "[all memories]",
  "notes_context": "[all notes]",
  "combined": true
}

Tip: Think of Aggregate as the “summary” step. It pools all items from the previous step so the AI Agent receives one clean input.

6 AI Memory Agent

What it does: This is the brain. The AI Agent reads the user’s message, your system prompt, and all the context from memories and notes. It decides what to respond, what to save, and which tools to call.

How to configure:

  • Add an “AI Tools Agent” node (@n8n/n8n-nodes-langchain.agent)
  • Set agentOptions.systemPrompt to the following:
You are an AI assistant with persistent memory capabilities. Your role is to:

1. MEMORY MANAGEMENT:
   - Extract and save important facts about the user for long-term recall
   - Format memories as: [DATE] - [TOPIC]: [DETAIL]
   - Save to 'Save Memory to Google Docs' when you learn something important

2. NOTE TAKING:
   - Capture actionable items, reminders, or temporary notes
   - Format notes as: [DATE] [TIME] - [NOTE]
   - Save to 'Save Note to Google Docs' when user mentions something to remember

3. CONTEXT AWARENESS:
   - Review loaded memories and notes before responding
   - Reference past conversations naturally
   - Acknowledge when you remember something about the user

4. RESPONSE GUIDELINES:
   - Be helpful, personable, and concise
   - If unsure, ask clarifying questions
   - Never make up information not in your context

Always use the provided tools to save important information.

Tool attachments: Connect the Session Memory Buffer, GPT-4o Mini LLM, and the two Save tools (Save Memory, Save Note). The agent will automatically call these tools based on its logic.

Data that flows out:

{
  "output": "Thanks Sarah! I've noted that you prefer oat milk lattes. I'll remember that for next time we chat. Is there anything else I can help with?",
  "tool_calls": [
    { "tool": "Save Memory to Google Docs", "input": { "topic": "Preference", "detail": "Oat milk lattes, no sugar" } }
  ]
}

Tip: The system prompt is where you define the AI’s personality and its rules for memory management. You can customize this heavily, make it more casual, more formal, more technical, whatever fits your use case.

7 GPT-4o Mini

What it does: The language model that powers the agent. GPT-4o-mini is fast, cheap (~$0.15 per 1K tokens), and smart enough for most chatbot tasks.

How to configure:

  • Add an “OpenAI Chat Model” node (@n8n/n8n-nodes-langchain.lmChatOpenAi)
  • Authenticate with your OpenAI API key
  • Set model to "gpt-4o-mini"
  • Set temperature to 0.7 (keeps responses natural but consistent)

Data flow: The Agent sends prompts to this node, which returns generated text. The node is “read-only” from the Agent’s perspective, it doesn’t make decisions, just generates language.

Tip: If you want more creative responses, increase temperature to 0.9. If you want more deterministic responses, lower it to 0.3. For memory-critical tasks, I’d recommend 0.5 to 0.7.

8 Session Memory Buffer

What it does: Stores the last 10 messages in the conversation (configurable). This gives the AI short-term context within a single chat session, complementing the long-term Google Docs memory.

How to configure:

  • Add a “Memory Buffer Window” node (@n8n/n8n-nodes-langchain.memoryBufferWindow)
  • Set bufferSize to 10 (keeps the last 10 messages)

Data that flows out:

{
  "history": [
    { "role": "user", "content": "Hey, remember I prefer oat milk?" },
    { "role": "assistant", "content": "I'll remember that!" },
    ...
  ]
}

Tip: The Session Memory Buffer is separate from the long-term Google Docs memory. Use bufferSize 10 to 20 for natural conversations. If you set it higher (50+), you might hit token limits on OpenAI, increasing costs.

9 Save Memory to Google Docs

What it does: A Google Docs node that appends new long-term memories. When the AI Agent decides to save something important, it calls this tool.

How to configure:

  • Add a “Google Docs” node (different from the retrieval nodes)
  • Authenticate with your Google account
  • Set resource to "document"
  • Set documentId to YOUR_GOOGLE_DOC_ID_MEMORIES
  • Set option to "appendText"
  • Set text to: ={{ "[" + new Date().toLocaleDateString() + "] - " + $json.input.topic + ": " + $json.input.detail }}

Example append:

[04/08/2026] - Preference: Oat milk lattes, no sugar

Tip: The expression creates a timestamp automatically. Each memory is on a new line, making the doc easy to scan.

10 Save Note to Google Docs

What it does: A Google Docs node for temporary notes. When the AI wants to save a reminder or action item, it calls this.

How to configure:

  • Add another “Google Docs” node (separate from Save Memory)
  • Authenticate with your Google account
  • Set resource to "document"
  • Set documentId to YOUR_GOOGLE_DOC_ID_NOTES
  • Set option to "appendText"
  • Set text to: ={{ "[" + new Date().toLocaleDateString() + " " + new Date().toLocaleTimeString() + "] - " + $json.input }}

Example append:

[04/08/2026 14:32:15] - User asked about Telegram integration

Tip: This node includes both date and time, since notes are usually time-sensitive. Notes doc grows fast, you might clean it out monthly or weekly depending on volume.

11 Send Telegram Reply

What it does: Sends the AI’s response to Telegram. Optional, but great for testing or if you want users to chat via Telegram instead of the n8n web UI.

How to configure:

  • Add an “HTTP Request” node (@n8n-nodes-base.httpRequest)
  • Set method to POST
  • Set url to: https://api.telegram.org/bot{{ $env.TELEGRAM_BOT_TOKEN }}/sendMessage
  • Add body parameters:
  • chat_id: YOUR_TELEGRAM_CHAT_ID
  • text: ={{ $json.output }}

Tip: Get your Telegram Bot Token from BotFather on Telegram. Get your Chat ID by messaging the bot and calling /getchatid (if your bot has that command) or using a debug service. If you’re not using Telegram, you can delete this node entirely. The workflow still works.

12 Format Chat Response

What it does: Formats the AI’s output for the n8n chat interface. This is optional if you’re only using Telegram, but it’s useful for testing.

How to configure:

  • Add a “Set” node (@n8n-nodes-base.set)
  • Set mode to "map"
  • Add assignment: response = ={{ $json.output }}

Data that flows out:

{
  "response": "Thanks Sarah! I've noted that you prefer oat milk lattes. I'll remember that for next time."
}

Tip: This node is simple, but it’s important for keeping the chat interface happy. It ensures the response is in the expected format.

The Data Structure

Let’s look at how data flows through the system, using a real example with Sarah:

Initial state (empty memories and notes):

Google Docs - Long-Term Memories:
(empty)

Google Docs - Notes:
(empty)

Sarah sends her first message:

User: "Hi! I'm Sarah from Chicago. I work in product management and I love oat milk lattes."

The workflow retrieves (empty context):

memories_context: ""
notes_context: ""

AI Agent decides to save key facts:

Tool call: Save Memory to Google Docs
Input: { topic: "Name", detail: "Sarah" }
Input: { topic: "Timezone", detail: "America/Chicago" }
Input: { topic: "Job", detail: "Product Manager" }
Input: { topic: "Preference", detail: "Oat milk lattes" }

Google Docs after first conversation:

Google Docs - Long-Term Memories:
[04/08/2026] - Name: Sarah
[04/08/2026] - Timezone: America/Chicago
[04/08/2026] - Job: Product Manager
[04/08/2026] - Preference: Oat milk lattes

Google Docs - Notes:
[04/08/2026 14:35:22] - User wants to learn n8n automation

Sarah’s next message (tomorrow):

User: "Hey, can you help me with n8n workflows?"

The workflow now retrieves:

memories_context: "[04/08/2026] - Name: Sarah\n[04/08/2026] - Timezone: America/Chicago\n[04/08/2026] - Job: Product Manager\n[04/08/2026] - Preference: Oat milk lattes"

notes_context: "[04/08/2026 14:35:22] - User wants to learn n8n automation"

AI response:

Output: "Hey Sarah! Of course, I'd love to help with your n8n workflows. Given that you're a PM at TechCorp in Chicago, I'm guessing you're looking to automate some processes for your team. What kind of workflows are you thinking about?"

Notice how the AI naturally references Sarah by name, acknowledges her role, and connects her earlier interest in n8n to the current question. That’s persistent memory in action.

Full System Flow

Here’s the complete end-to-end journey:

┌─ Start: User sends message via Chat Trigger or Telegram ──┐
│                                                             │
├─ Parallel: Load Memories from Google Docs                 │
│ └─ Retrieve all historical facts about user                │
│                                                             │
├─ Parallel: Load Notes from Google Docs                    │
│ └─ Retrieve session context and recent reminders           │
│                                                             │
├─ Merge: Combine both memory sources                       │
│ └─ Creates array: [memories_obj, notes_obj]               │
│                                                             │
├─ Aggregate: Consolidate into single context               │
│ └─ Pools all items into one data structure                │
│                                                             │
├─ AI Memory Agent (receives):                              │
│ ├─ User message                                            │
│ ├─ All long-term memories                                 │
│ ├─ All notes from this session                            │
│ ├─ Last 10 messages from Session Memory Buffer            │
│ ├─ System prompt (memory management rules)                │
│ └─ Connection to GPT-4o-mini and tools                    │
│                                                             │
├─ AI Decision Making:                                      │
│ ├─ Read context and user message                          │
│ ├─ Generate response                                       │
│ ├─ Decide what facts to save (→ Save Memory tool)         │
│ └─ Decide what notes to capture (→ Save Note tool)        │
│                                                             │
├─ Parallel: Save Memory to Google Docs                     │
│ └─ Append new facts (if AI decided to save)               │
│                                                             │
├─ Parallel: Save Note to Google Docs                       │
│ └─ Append new notes (if AI decided to save)               │
│                                                             │
├─ Output to Chat:                                          │
│ ├─ Format Chat Response → n8n Web UI                     │
│ └─ Send Telegram Reply → User's Telegram                 │
│                                                             │
└─ Complete: User receives response & AI remembers ──────────┘

Testing Your Workflow

Now that your workflow is built, let’s test it thoroughly:

Test Plan

  1. Deploy the workflow and activate it in n8n
  2. Open the Chat Trigger and test with a simple message: "Hi, my name is Sarah and I like coffee."
  3. Check the Google Docs: The Memories doc should now have a new entry with Sarah’s name
  4. Send another message: "What do I like to drink?" The AI should reference the coffee preference from the previous message
  5. Test Telegram output (if enabled) by checking your Telegram chat, the response should arrive there too
  6. Clear the Notes doc and send a message with a reminder: "Remind me to follow up with the marketing team tomorrow." Check that the note appears in the Notes doc
  7. Simulate a delay: Wait 10 minutes, come back, and test that the AI still remembers Sarah. This confirms persistence

Troubleshooting Table

Issue Likely Cause Fix
Chat Trigger shows “Webhook not working” Workflow not saved or deployed Click Save, then Deploy. Check that the webhook URL is active in the node.
Google Docs nodes fail with auth error OAuth2 credential not connected or expired Re-authenticate the Google Docs credential. Grant permission for Docs read/write.
AI response is generic, not remembering user Memories not being retrieved or system prompt unclear Check that Load Memories node is pulling data. Review system prompt in AI Agent node for clarity.
Memory saves fail silently (no error, but doc not updated) Google Doc ID is incorrect or doc doesn’t exist Verify Document ID in Save Memory and Save Note nodes. Double-check the URL in Google Docs.
Telegram message doesn’t send Bot token invalid or chat ID missing Confirm bot token with BotFather. Test chat ID manually using curl or Postman.
Workflow is slow (>5 second response) Large memory doc or network latency Archive old memories to a separate doc. Consider pagination in future versions.

Frequently Asked Questions

How much data can Google Docs store?

Google Docs has a 50MB file size limit, which translates to roughly 10 to 20 million words. For a personal chatbot, you’d need to chat 100+ times daily for years to hit that limit. For multi-user systems, consider archiving old memories after 6 months.

Why Google Docs instead of a real database?

Simplicity. No backend servers, no authentication headaches, no costs, and you can read/edit memories by hand. For production systems with thousands of users, you’d want PostgreSQL or MongoDB. For personal projects and small teams, Google Docs is perfect.

Can multiple users use the same workflow?

Yes, but you’d want to create separate memory docs per user (or per user-group). Otherwise, all memories get mixed together. A simple fix is to add a User ID prefix in each memory entry: [04/08/2026] [user-sarah] - Preference: Oat milk.

What if I want to use a different LLM instead of GPT-4o-mini?

Easy. Replace the “GPT-4o Mini” node with any other LLM node that n8n supports: Claude (Anthropic), Gemini (Google), Llama (Meta), or even local models. The system prompt stays the same. Just swap the node and re-authenticate.

How do I ensure memory data is private?

The memories are stored in your Google Docs, which means Google has access (per their privacy policy). If you need end-to-end encryption, deploy n8n self-hosted and use your own database with encryption at rest. For most use cases, treating Google Docs like email (encrypted in transit, encrypted at rest on Google’s servers) is sufficient.

What if the AI forgets something it should remember?

This usually means the system prompt isn’t clear enough about what to save. Revisit the “MEMORY MANAGEMENT” section of the system prompt and be more explicit. Example: add “Save names, preferences, job titles, and timezone. Save reminders and follow-ups as notes.” You can also manually add memories to the Google Doc yourself.

Ready to Deploy This Workflow?

Get the complete, ready-to-import JSON file with all the configurations, plus detailed setup guides for OpenAI, Google Docs, and Telegram. Import in seconds and start building.

Get the Workflow & Setup Guide

Includes step-by-step credential setup, testing checklist, and common customizations.

What’s Next?

You’ve built a powerful memory-driven chatbot. Here are four directions you can take it:

  1. Add Slack Integration: Instead of (or in addition to) Telegram, receive and respond to Slack DMs. Users stay in Slack, and memories persist across platforms.
  2. Multi-User Memory Isolation: Spin up separate memory docs per user, or implement a shared “team knowledge base” doc that all users contribute to. Great for support teams.
  3. Export Memory Analytics: Create a separate workflow that reads the memory doc weekly and generates a summary email. “Sarah asked 12 questions about n8n, preferred 5 templates, and wants to learn automation.”
  4. Archive Old Memories: Set up a scheduled n8n workflow that runs monthly, archives memories older than 6 months to a separate “Archive” doc, and clears the active memory doc. Keeps performance snappy.
n8n
AI Agent
Memory Management
Google Docs
GPT-4o
Chatbot
Telegram
LLM Integration
Automation